Let's build GPT: from scratch, in code, spelled out.
Description
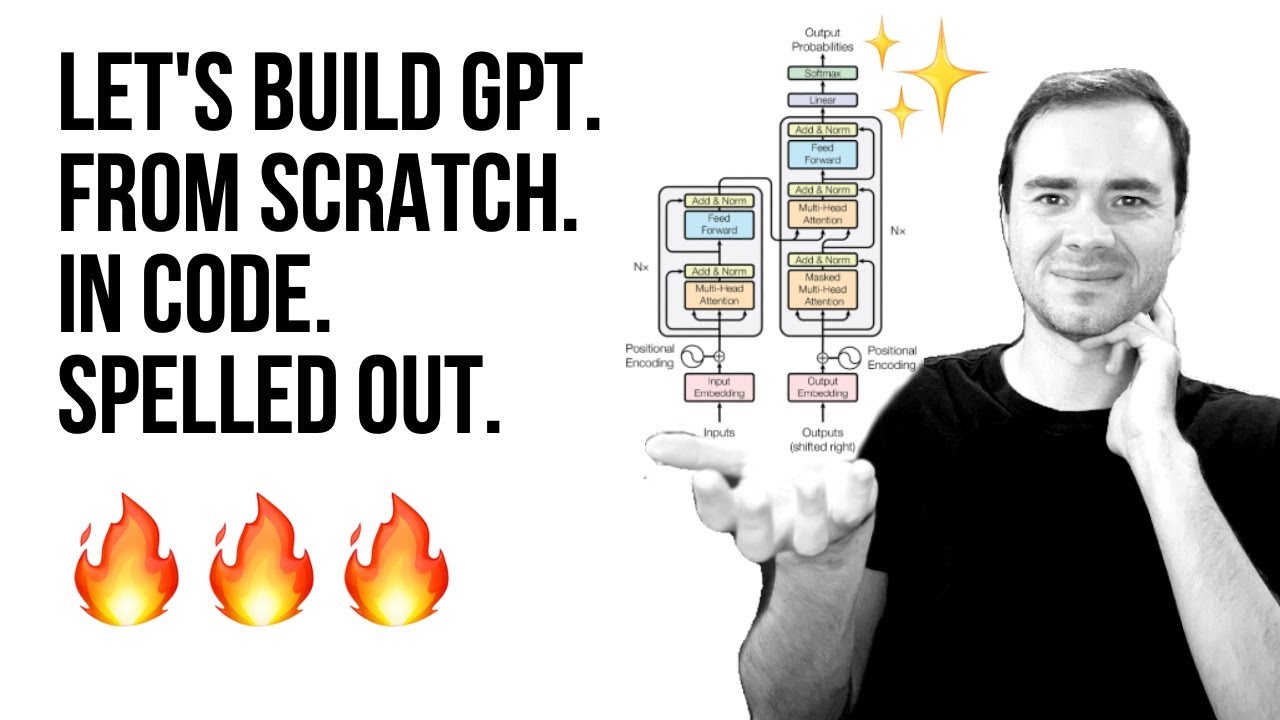
We build a Generatively Pretrained Transformer (GPT), following the paper "Attention is All You Need" and OpenAI's GPT-2 / GPT-3. We talk about connections to ChatGPT, which has taken the world by storm. We watch GitHub Copilot, itself a GPT, help us write a GPT (meta :D!) . I recommend people watch the earlier makemore videos to get comfortable with the autoregressive language modeling framework and basics of tensors and PyTorch nn, which we take for granted in this video. Links: - Google colab for the video: https://colab.research.google.com/drive/1JMLa53HDuA-i7ZBmqV7ZnA3c_fvtXnx-?usp=sharing - GitHub repo for the video: https://github.com/karpathy/ng-video-lecture - Playlist of the whole Zero to Hero series so far: https://www.youtube.com/watch?v=VMj-3S1tku0&list=PLAqhIrjkxbuWI23v9cThsA9GvCAUhRvKZ - nanoGPT repo: https://github.com/karpathy/nanoGPT - my website: https://karpathy.ai - my twitter: https://twitter.com/karpathy - our Discord channel: https://discord.gg/3zy8kqD9Cp Supplementary links: - Attention is All You Need paper: https://arxiv.org/abs/1706.03762 - OpenAI GPT-3 paper: https://arxiv.org/abs/2005.14165 - OpenAI ChatGPT blog post: https://openai.com/blog/chatgpt/ - The GPU I'm training the model on is from Lambda GPU Cloud, I think the best and easiest way to spin up an on-demand GPU instance in the cloud that you can ssh to: https://lambdalabs.com . If you prefer to work in notebooks, I think the easiest path today is Google Colab. Suggested exercises: - EX1: The n-dimensional tensor mastery challenge: Combine the `Head` and `MultiHeadAttention` into one class that processes all the heads in parallel, treating the heads as another batch dimension (answer is in nanoGPT). - EX2: Train the GPT on your own dataset of choice! What other data could be fun to blabber on about? (A fun advanced suggestion if you like: train a GPT to do addition of two numbers, i.e. a+b=c. You may find it helpful to predict the digits of c in reverse order, as the typica
Summary
Generated by gpt-5.6-terraAt-a-Glance
- Verdict: Watch fully
- Core thesis: Karpathy builds a decoder-only GPT from a bigram baseline into a scaled transformer to show that modern GPT pre-training is architecturally straightforward but operationally dependent on scale, data, and a separate alignment pipeline.
- Why it matters: This is an unusually clear implementation-level explanation of the core model beneath LLM products: causal attention, transformer blocks, training loops, scaling behavior, and the critical distinction between pre-training and assistant alignment.
- Best use: Use it as a technical foundation for evaluating model architectures, debugging custom LLM training/inference assumptions, and separating what can be reproduced with an open model stack from what requires serious data, compute, and post-training infrastructure.
Executive Summary
The video derives a GPT-style language model in PyTorch from first principles, using a character-level Tiny Shakespeare dataset rather than attempting to reproduce ChatGPT. It starts with tokenization, random training batches, next-token cross-entropy, probabilistic sampling, and a bigram model, then incrementally adds the components that make a transformer useful: positional embeddings, causal self-attention, multi-head attention, feed-forward networks, residual connections, layer normalization, dropout, and depth.
The central technical argument is that causal self-attention is a learned, data-dependent communication mechanism. Each token generates queries, keys, and values; query-key dot products determine which prior tokens matter; a lower-triangular mask prevents future-token leakage; softmax converts scores into aggregation weights; and values are combined into each token’s updated representation. Multiple heads let the model maintain distinct communication channels, while feed-forward layers let each token compute over the information it gathered.
The practical lesson is that architecture alone is not ChatGPT. The completed toy transformer reaches a validation loss of 1.48 after scaling to six layers, six heads, 384 embedding dimensions, 256-character context, batch size 64, and 0.2 dropout, trained for roughly 15 minutes on an A100. It produces Shakespeare-shaped but semantically weak text, illustrating both the value of scaling and the limits of a 10M-parameter model trained on roughly 1M characters.
Karpathy closes by distinguishing pre-training from post-training. Pre-training teaches a decoder-only transformer to continue internet-like text; it does not inherently create a useful assistant. ChatGPT-style behavior requires supervised instruction tuning, human preference rankings, a reward model, and PPO-based optimization. The NanoGPT codebase therefore demonstrates the pre-training core, while the more difficult proprietary moat lies in data, compute infrastructure, and alignment/post-training systems.
Key Takeaways
- Claim: A GPT is fundamentally an autoregressive next-token predictor, not a system directly trained to answer questions or perform tasks. | Evidence: The model receives a sequence of tokens and predicts the next token at every position; generation repeatedly samples the next-token distribution and appends the result. The initial bigram model predicts using only the current token identity, while later transformer layers incorporate prior context. | Implication: When assessing an LLM product, distinguish base-model continuation capability from the instruction-following, tool-use, safety, and workflow behavior added through post-training and system design. | Caveat: A next-token objective can produce capable behavior at sufficient scale, but pre-training alone yields an unconstrained document completer whose response to a prompt may be undefined or unhelpful.
- Claim: Causal self-attention is the key mechanism that lets tokens selectively retrieve useful information from prior context. | Evidence: Each token projects its representation into query, key, and value vectors; query-key dot products create pairwise affinities, a causal lower-triangular mask blocks future positions, softmax normalizes the scores, and the resulting weights aggregate value vectors. Karpathy characterizes query as 'what am I looking for,' key as 'what do I contain,' and value as 'what I communicate if selected.' | Implication: For agent and orchestration systems, attention is best understood as learned context routing: performance depends not merely on having more context, but on representations and mechanisms that retrieve the right context under the task’s allowed information flow. | Caveat: Attention itself has no inherent notion of token order or spatial position; positional embeddings must be added explicitly.
- Claim: The causal mask determines whether a transformer can generate autoregressively or instead encode a fully visible input. | Evidence: The decoder-only model masks the upper triangle so each position can attend only to itself and preceding tokens, preventing answer leakage during next-token prediction. For sentiment classification or other encoding tasks, removing the mask lets all tokens communicate. In encoder-decoder translation, an unmasked encoder processes source text and decoder cross-attention conditions generation on it. | Implication: Architecture choice should follow information-flow requirements: use causal models for streaming/generation, bidirectional encoding where full input inspection is valid, and cross-attention where generation must condition on an external structured source. | Caveat: Calling something an encoder or decoder is not primarily about the block name; it follows from connectivity and whether future positions are masked.
- Claim: A functional transformer alternates communication and computation, then needs residual pathways and normalization to scale in depth. | Evidence: Multi-head attention provides parallel communication channels; position-wise feed-forward networks let each token transform the collected information. Stacking these blocks initially creates optimization difficulty, which residual additions address by providing a 'gradient superhighway.' Pre-layer normalization is then added before attention and feed-forward sublayers, with a final layer norm before vocabulary decoding. | Implication: When adapting or implementing transformer components, treat residual structure, normalization placement, projections, and feed-forward width as core trainability decisions rather than cosmetic implementation details. | Caveat: The tutorial uses a pre-norm layout, noting that this differs from the original 2017 paper’s post-norm presentation but is common in later practice.
- Claim: Scaling a small transformer materially improves next-token modeling, but output quality remains constrained by data, tokenizer, model size, and compute. | Evidence: The model progresses from approximately 2.5 validation loss for the bigram baseline to 2.4 with one attention head, 2.28 with multi-head attention, 2.24 with feed-forward computation, about 2.06 with residuals and layer norm, and 1.48 after scaling. The final configuration uses six layers, six heads, 384 embeddings, 256-character context, batch size 64, and 0.2 dropout; it trains in roughly 15 minutes on an A100 GPU. | Implication: A toy implementation is valuable for understanding and prototyping, but production-quality model behavior should not be inferred from architectural correctness alone; training economics and data quality dominate quickly. | Caveat: Even at 1.48 validation loss, the generated Shakespeare is stylistically recognizable but often nonsensical. Karpathy explicitly advises against attempting the scaled configuration on CPU or a typical MacBook without reducing dimensions/layers.
- Claim: ChatGPT-like assistants require a post-training alignment stack beyond base-model pre-training. | Evidence: Karpathy describes pre-training as training on a large internet corpus to complete documents. He then outlines a post-training sequence: supervised examples formatted as user question plus assistant answer; human raters ranking candidate outputs; a reward model trained on those preferences; and PPO reinforcement learning to optimize the model toward high predicted reward. | Implication: For Ken’s AI operations work, base-model selection is only one layer: reliable assistants require explicit task data, evaluation criteria, preference/safety policies, and iterative post-training or runtime control mechanisms. | Caveat: He notes that much of the relevant alignment data is proprietary and that the exact public details are incomplete; NanoGPT focuses on pre-training rather than replicating the full assistant-training pipeline.
- Claim: The core GPT architecture can be expressed compactly, while production training complexity lives around the model. | Evidence: The tutorial’s completed educational implementation is roughly 200 lines, and Karpathy describes NanoGPT’s principal files as a model definition and a training script. The production-oriented training file adds checkpointing, pretrained-weight loading, learning-rate decay, compilation, weight-decay parameter handling, and distributed multi-GPU training. | Implication: Evaluate LLM initiatives as two separate engineering problems: model logic may be understandable and portable, but reproducible operations require data pipelines, distributed systems, experiment management, checkpointing, and evaluation infrastructure. | Caveat: Compact code does not imply simple operations: GPT-3-scale training involves a 175B-parameter model trained on 300B tokens and typically requires thousands of GPUs communicating together.
Detailed Brief
Training-data and inference mechanics
- Claims: Character-level tokenization maps each of the 65 distinct Tiny Shakespeare characters to an integer and back; real GPT systems generally use subword tokenizers instead.; A training sequence contains multiple supervised examples: for a block of length 8, the model predicts each next token using contexts ranging from length 1 through 8.; Batches are independent sampled chunks stacked for GPU parallelism; examples across the batch dimension do not communicate.; At inference, generation samples from softmax probabilities with multinomial sampling rather than deterministically choosing the top logit.
- Evidence: Tiny Shakespeare is roughly a 1 MB corpus containing about 1M characters; the held-out validation split is the final 10% of the corpus.; GPT-2’s tokenizer is described as having roughly 50,256 tokens, versus the tutorial’s 65-character vocabulary; this trades a larger vocabulary for shorter sequences.; The generator crops its input context to the configured block size because learned positional embeddings only exist through that maximum position.
- Caveats: The validation split is a simple contiguous 90/10 split rather than a broader benchmark; its role is primarily to expose overfitting on this tutorial corpus.; Character-level modeling makes the pedagogical code simpler but is not representative of production tokenizer efficiency or semantic granularity.
- Implications: Context-window limits are architectural and training-time constraints, not merely UI parameters.; Sampling behavior is part of the model product: the same prompt can yield different outputs because generation draws from a probability distribution.
Numerical and implementation safeguards
- Claims: Scaled dot-product attention divides query-key scores by the square root of head size to preserve manageable variance before softmax.; Without scaling, large-magnitude attention scores cause softmax to become excessively one-hot, leading each token to retrieve almost exclusively from one location at initialization.; Dropout regularizes the scaled model by randomly zeroing portions of intermediate activations and some attention weights during training.; Evaluation should use evaluation mode and no-gradient execution, both to respect layers whose behavior differs at inference and to avoid unnecessary memory use.
- Evidence: The tutorial adds 0.2 dropout when scaling the model, including after attention softmax and before residual returns.; Karpathy contrasts layer normalization with batch normalization: layer norm normalizes each token’s feature vector and therefore does not need batch-level running statistics or separate train/test behavior.
- Caveats: The stated intuition that dropout trains an ensemble of subnetworks is a useful framing, but it is not a substitute for measuring held-out performance and generation quality.; Hyperparameter settings demonstrated on Tiny Shakespeare are instructional starting points, not universal production defaults.
- Implications: Training instability should first prompt checks of normalization, residual topology, learning rate, attention-score scaling, context length, and regularization before assuming the base architecture is wrong.; Operational model evaluation should track both loss and task-relevant output quality; lower language-model loss can still leave outputs unsuitable for end users.
Scale comparison and the boundary of reproducibility
- Claims: The tutorial’s final model is architecturally similar to GPT-family decoder-only transformers but differs radically in scale.; The major distinction between a toy transformer and ChatGPT is not a mysterious new core architecture; it is scale plus the separate data and alignment pipeline.
- Evidence: The final Tiny Shakespeare model has about 10M parameters and is trained on roughly 1M characters, estimated as about 300,000 GPT-style subword tokens.; The video compares this with GPT-3’s 175B parameters and 300B training tokens—roughly a million-fold token increase relative to the tutorial estimate—and notes that contemporary training may exceed 1T tokens.; NanoGPT is presented as reproducing GPT-2-small-scale behavior and loading released OpenAI weights, supporting the claim that its core implementation is arranged correctly.
- Caveats: The speaker’s scale comparisons are illustrative and tokenizer-dependent; character counts and subword-token counts are not directly interchangeable.; Matching a published checkpoint or architecture does not reproduce proprietary datasets, filtering, training recipes, preference data, safety mitigation, or deployment controls.
- Implications: Build-vs-buy decisions should avoid treating an open implementation of transformer code as equivalent to owning a competitive foundation-model pipeline.; The accessible opportunity is often to adapt capable pretrained models through retrieval, tools, post-training, and control planes rather than to recreate frontier pre-training.
Notable Concepts & Terms
- Decoder-only transformer: The GPT-style architecture used here: a causally masked transformer that predicts and samples the next token from prior tokens.
- Causal mask / lower-triangular mask: The mechanism that prevents future tokens from affecting current predictions, enabling valid autoregressive generation.
- Query, Key, Value (QKV): The learned projections that define what a token seeks, what it offers, and the information it contributes when attended to.
- Multi-head attention: Parallel attention channels with separate projections, allowing different relational patterns to be retrieved simultaneously.
- Residual connection: An additive skip pathway around attention and feed-forward transformations that improves gradient flow and deep-network optimization.
- Pre-norm layer normalization: Applying layer norm before attention and feed-forward sublayers; the tutorial uses this modernized formulation for improved trainability.
- Cross-attention: Attention in which decoder queries read keys and values from an external encoded source, used to condition generation in encoder-decoder tasks such as translation.
- RLHF / PPO post-training: The assistant-alignment process described: train on demonstrations, collect human rankings, fit a reward model, then use PPO to optimize outputs toward human preferences.
Operator Notes / Why Ken Should Care
- Use this as the shared technical baseline before making architecture or vendor claims about 'GPT-like' systems; require teams to specify tokenizer, context window, causal versus bidirectional attention, post-training method, and inference sampling policy.
- For any custom model effort, separate the roadmap and budget into pre-training, post-training/alignment, evaluation, serving, and distributed-training operations rather than treating them as one model-training task.
- Avoid benchmarking model quality solely with training loss or short samples; establish held-out task evaluations, preference tests, safety tests, and long-context failure tests.
- For product systems, prioritize leveraging pretrained models with explicit runtime controls, retrieval/context design, tool policies, and evaluation loops over training a base model from scratch unless proprietary data and compute economics clearly justify it.
- If reviewing an implementation, audit causal masking and context truncation first: a masking error leaks future information during training, while context-window mismatch can silently degrade generation.
Source/Metadata
- Title: Let's build GPT: from scratch, in code, spelled out.
- Transcript words: 31315
- Duration seconds: 6980
- Timestamp note: No usable timestamps or chapter markers were present in the supplied transcript.
Transcript
Hi everyone. By now, you have probably heard of ChatGPT. It has taken the world and the AI community by storm, and it is a system that allows you to interact with an AI and give it text-based tasks. For example, we can ask ChatGPT to write us a small haiku about how important it is that people understand AI, and then they can use it to improve the world and make it more prosperous. So when we run this, AI knowledge brings prosperity for all to see, embrace its power. Okay, not bad. And so you could see that ChatGPT went from left to right and generated all these words sequentially. Now I asked it already the exact same prompt a little bit earlier, and it generated a slightly different outcome. AI's power to grow, ignorance holds us back, learn, prosperity waits. Pretty good in both cases, and slightly different. So you can see that ChatGPT is a probabilistic system, and for any one prompt it can give us multiple answers, replying to it. Now this is just one example of a prompt. People have come up with many, many examples, and there are entire websites that index interactions with ChatGPT. And many of them are quite humorous. Explain HTML to me like I'm a dog. Write release notes for chess two. Write a note about Elon Musk buying Twitter, and so on. As an example, please write a breaking news article about a leaf falling from a tree. In a shocking turn of events, a leaf has fallen from a tree in the local park. Witnesses report that the leaf, which was previously attached to a branch of a tree, detached itself and fell to the ground. Very dramatic. So you can see that this is a pretty remarkable system, and it is what we call a language model because it models the sequence of words, or characters, or tokens more generally, and it knows how words follow each other in the English language. And so from its perspective, what it is doing is completing the sequence. So I give it the start of a sequence, and it completes the sequence with the outcome. And so it's a language model in that sense. Now, I would like to focus on the under-the-hood components of what makes ChatGPT work. So what is the neural network under the hood that models the sequence of these words? And that comes from this paper called Attention Is All You Need. In 2017, a landmark paper in AI produced and proposed the transformer architecture. So GPT is short for generatively pre-trained transformer. So transformer is the neural net that actually does all the heavy lifting under the hood. It comes from this paper in 2017. Now, if you read this paper, this reads like a pretty random machine translation paper. And that's because I think the authors didn't fully anticipate the impact that the transformer would have on the field. And this architecture that they produced in the context of machine translation, in their case, actually ended up taking over the rest of AI in the next five years after. And so this architecture, with minor changes, was copy-pasted into a huge amount of applications in AI in more recent years. And that includes at the core of ChatGPT. Now, what I'd like to do now is I'd like to build out something like ChatGPT. But we're not going to be able to, of course, reproduce ChatGPT. This is a very serious production-grade system. It is trained on a good chunk of the internet. And then there's a lot of pre-training and fine-tuning stages to it. And so it's very complicated. What I'd like to focus on is just to train a transformer-based language model. And in our case, it's going to be a character-level language model. I still think that is very educational with respect to how these systems work. So I don't want to train on a chunk of the internet. We need a smaller dataset. In this case, I propose that we work with my favorite toy dataset. It's called Tiny Shakespeare. And what it is, is a concatenation of all of the works of Shakespeare, in my understanding. And so this is all of Shakespeare in a single file. This file is about one megabyte, and it's just all of Shakespeare. And what we are going to do now is we're going to model how these characters follow each other. So, for example, given a chunk of these characters like this, given some context of characters in the past, the transformer neural network will look at the characters that I've highlighted. And it's going to predict that G is likely to come next in the sequence. And it's going to do that because we're going to train that transformer on Shakespeare. And it's just going to try to produce character sequences that look like this. And in that process, it's going to model all the patterns inside this data. So once we've trained the system, I'd just like to give you a preview. We can generate infinite Shakespeare. And of course, it's a fake thing that looks kind of like Shakespeare. Apologies for... There's some jank that I'm not able to resolve here. But you can see how this is going character by character. And it's predicting Shakespeare-like language. So, verily, my lord, the sights have left thee, again, the king, coming with my curses with precious pale. And then Tranius says something else, etc. And this is just coming out of the transformer in a very similar manner as it would come out in ChatGPT. In our case, character by character. In ChatGPT, it's coming out on the token-by-token level. And tokens are these little subword pieces. So they're not word level, they're kind of word-chunk level. And now, I've already written this entire code to train these transformers. And it is in a GitHub repository that you can find. And it's called NanoGPT. So NanoGPT is a repository that you can find on my GitHub. And it's a repository for training transformers on any given text. And what I think is interesting about it, because there are many ways to train transformers, but this is a very simple implementation. So it's just two files of 300 lines of code each. One file defines the GPT model, the transformer, and one file trains it on some given text dataset. And here, I'm showing that if you train it on an open web text dataset, which is a fairly large dataset of web pages, then I reproduce the performance of GPT-2. So GPT-2 is an early version of OpenAI's GPT from 2017, if I recall correctly. And I've only so far reproduced the smallest, 124 million parameter model. But basically, this is just proving that the code base is correctly arranged. And I'm able to load the neural network weights that OpenAI released later. So you can take a look at the finished code here in NanoGPT. But what I would like to do in this lecture is I would like to write this repository from scratch. So we're going to begin with an empty file. And we're going to define a transformer piece by piece. We're going to train it on the Tiny Shakespeare dataset. So GPT-2 is an early version of OpenAI's GPT from 2017, if I recall correctly. And I've only reproduced the smallest, 124 million parameter model, so far. But this is just proving that the code base is correctly arranged. And I'm able to load the neural network weights that OpenAI released later. So you can take a look at the finished code here in NanoGPT. But what I would like to do in this lecture is write this repository from scratch. So we're going to begin with an empty file. And we're going to define a transformer piece by piece. We're going to train it on the Tiny Shakespeare dataset. And we'll see how we can then generate infinite Shakespeare. And of course, this can copy-paste to any arbitrary text dataset that you like. But my goal here is to make you understand and appreciate how, under the hood, ChatGPT works. And really, all that's required is a proficiency in Python and some basic understanding of calculus and statistics. And it would help if you also see my previous videos on the same YouTube channel, in particular my Make More series, where I define smaller and simpler neural network language models. So multilayered perceptrons and so on. It really introduces the language modeling framework. And then here in this video, we're going to focus on the transformer neural network itself. Okay, so I created a new Google Colab Jupyter notebook here. And this will allow me to later easily share this code that we're going to develop together with you so you can follow along. So this will be in the video description. I'll see you later. Now, here I've just done some preliminaries. I downloaded the dataset, the Tiny Shakespeare dataset, at this URL. And you can see that it's about a one megabyte file. Then here I open the input.txt file and just read in all the text as a string. And we see that we are working with roughly one million characters. And the first 1,000 characters, if we just print them out, are what you would expect. This is the first 1,000 characters of the Tiny Shakespeare dataset, roughly up to here. So, so far, so good. Next, we're going to take this text. And the text is a sequence of characters in Python. So when I call the set constructor on it, I'm just going to get the set of all the characters that occur in this text. And then I call list on that to create a list of those characters instead of just a set so that I have an ordering, an arbitrary ordering. And then I sort that. So we get all the characters that occur in the entire dataset, and they're sorted. Now, the number of them is going to be our vocabulary size. These are the possible elements of our sequences. And we see that when I print here the characters, there's 65 of them in total. There's a space character and then all kinds of special characters and then capitals and lowercase letters. So that's our vocabulary. And that's the possible characters that the model can see or emit. Okay, so next, we would like to develop some strategy to tokenize the input text. Now, when people say tokenize, they mean convert the raw text as a string to some sequence of integers according to some vocabulary of possible elements. So as an example, here we are going to be building a character-level language model. So we're simply going to be translating individual characters into integers. So let me show you a chunk of code that does that for us. So we're building both the encoder and the decoder. And let me just talk through what's happening here. When we encode an arbitrary text like hi there, we're going to receive a list of integers that represents that string. So, for example, 46, 47, etc. And then we also have the reverse mapping. So we can take this list and decode it to get back the exact same string. So it's really just a translation to integers and back for arbitrary strings. And for us, it is done on a character level. Now, the way this was achieved is we just iterate over all the characters here and create a lookup table from the character to the integer and vice versa. And then to encode some string, we simply translate all the characters individually. And to decode it back, we use the reverse mapping and concatenate all of it. Now, this is only one of many possible encodings or many possible tokenizers. And it's a very simple one. But there are many other schemas that people have come up with in practice. So, for example, Google uses sentence piece. So sentence piece will also encode text into integers, but in a different schema and using a different vocabulary. And sentence piece is a subword tokenizer. And what that means is that you're not encoding entire words, but you're also not encoding individual characters. It's a subword unit level. And that's usually what's adopted in practice. For example, OpenAI also has this library called TickToken that uses a byte pair encoding tokenizer. And that's what GPT uses. And you can also just encode words into a local world into lists of integers. So as an example, I'm using the TickToken library here. I'm getting the encoding for GPT-2, or that was used for GPT-2. Instead of just having 65 possible characters or tokens, they have 50,000 tokens. And so when they encode the exact same string, hi there, we only get a list of three integers. But those integers are not between 0 and 64. They are between 0 and 50,256. So you can trade off the codebook size and the sequence lengths. So you can have very long sequences of integers with very small vocabularies. Or you can have short sequences of integers with very large vocabularies. And so typically, people use these subword encodings in practice. But I'd like to keep our tokenizer very simple. So we're using a character-level tokenizer. And that means that we have very small codebooks. We have very simple encode and decode functions. But we do get very long sequences as a result. But that's the level at which we're going to stick with this lecture because it's the simplest thing. Okay, so now that we have an encoder and a decoder, effectively a tokenizer, we can tokenize the entire training set of Shakespeare. So here's a chunk of code that does that. And I'm going to start to use the PyTorch library, and specifically the torch.tensor from the PyTorch library. So we're going to take all of the text in Tiny Shakespeare, encode it, and then wrap it into a torch.tensor to get the data tensor. We have very simple encode and decode functions. But we do get very long sequences as a result. But that's the level at which we're going to stick with this lecture because it's the simplest thing. Okay, so now that we have an encoder and a decoder, effectively a tokenizer, we can tokenize the entire training set of Shakespeare. So here's a chunk of code that does that. And I'm going to start to use the PyTorch library, and specifically the torch.tensor from the PyTorch library. So we're going to take all of the text in Tiny Shakespeare, encode it, and then wrap it into a torch.tensor to get the data tensor. So here's what the data tensor looks like when I look at just the first 1,000 characters, or the 1,000 elements of it. So we see that we have a massive sequence of integers. And this sequence of integers here is an identical translation of the first 1,000 characters here. So I believe, for example, that 0 is a newline character and maybe 1 is a space. Not 100% sure. But from now on, the entire data set of text is re-represented. It's just stretched out as a single, very large sequence of integers. Let me do one more thing before we move on here. I'd like to separate out our data set into a train and a validation split. So in particular, we're going to take the first 90% of the data set and consider that to be the training data for the transformer. And we're going to withhold the last 10% at the end of it to be the validation data. And this will help us understand to what extent our model is overfitting. So we're going to hide and keep the validation data on the side because we don't want just a perfect memorization of this exact Shakespeare. We want a neural network that creates Shakespeare-like text. And so it should be fairly likely for it to produce the actual stowed-away true Shakespeare text. And so we're going to use this to get a sense of the overfitting. Okay, so now we would like to start plugging these text sequences, or integer sequences, into the transformer so that it can train and learn those patterns. Now, the important thing to realize is we're never going to actually feed entire text into a transformer all at once. That would be computationally very expensive and prohibitive. So when we actually train a transformer on a lot of these data sets, we only work with chunks of the data set. And when we train the transformer, we sample random little chunks out of the training set and train on just chunks at a time. And these chunks have some kind of length and some maximum length. Now, the maximum length typically, at least in the code I usually write, is called block size. You can find it under different names, like context length or something like that. Let's start with the block size of just eight. And let me look at the first train data characters, the first block size plus one characters. I'll explain why plus one in a second. So this is the first nine characters in the sequence, in the training set. Now, what I'd like to point out is that when you sample a chunk of data like this, so say these nine characters out of the training set, this actually has multiple examples packed into it. And that's because all of these characters follow each other. And so what this thing is going to say when we plug it into a transformer is we're going to simultaneously train it to make prediction at every one of these positions. Now, in a chunk of nine characters, there are actually eight individual examples packed in there. So there's the example that when 18, in the context of 18, 47 likely comes next. In the context of 18 and 47, 56 comes next. In the context of 18, 47, 56, 57 can come next. And so on. So that's the eight individual examples. Let me actually spell it out with code. So here's a chunk of code to illustrate. X are the inputs to the transformer. It will just be the first block size characters. Y will be the next block size characters. So it's offset by one. And that's because Y are the targets for each position in the input. And then here I'm iterating over all the block size of eight. And the context is always all the characters in X up to T and including T. And the target is always the T-th character, but in the targets array Y. So let me just run this. And it spells out what I said in words. These are the eight examples hidden in a chunk of nine characters that we sampled from the training set. I want to mention one more thing. So we train on all the eight examples here with context between one all the way up to context of block size. And we train on that not just for computational reasons because we happen to have the sequence already, or something like that. It's not just done for efficiency. It's also done to make the transformer network be used to seeing contexts all the way from as little as one all the way to block size. And we'd like the transformer to be used to seeing everything in between. And that's going to be useful later during inference because while we're sampling, we can start the sampling generation with as little as one character of context. And the transformer knows how to predict the next character with all the way up to just context of one. And so then it can predict everything up to block size. And after block size, we have to start truncating because the transformer will never receive more than block size inputs when it's predicting the next character. Okay, so we've looked at the time dimension of the tensors that are going to be feeding into the transformer. There's one more dimension to care about, and that is the batch dimension. And so as we're sampling these chunks of text, every time we're going to feed them into a transformer, we're going to have many batches of multiple chunks of text that are all stacked up in a single tensor. And that's just done for efficiency, just so that we can keep the GPUs busy, because they are very good at parallel processing of data. And so we just want to process multiple chunks all at the same time. But those chunks are processed completely independently. They don't talk to each other, and so on. So let me just generalize this and introduce a batch dimension. Here's a chunk of code. Let me just run it, and then I'm going to explain what it does. So here, because we're going to start sampling random locations in the data sets to pull chunks from, I am setting the seed in the random number generator so that the numbers I see here are going to be the same numbers you see later, if you try to reproduce this. And so we just want to process multiple chunks all at the same time. But those chunks are processed completely independently. They don't talk to each other, and so on. So let me just generalize this and introduce a batch dimension. Here's a chunk of code. Let me just run it, and then I'm going to explain what it does. So here, because we're going to start sampling random locations in the data sets to pull chunks from, I am setting the seed in the random number generator so that the numbers I see here are going to be the same numbers you see later if you try to reproduce this. Now the batch size here is how many independent sequences we are processing every forward-backward pass of the transformer. The batch size, as I explained, is the maximum context length to make those predictions. So let's say batch size 4, batch size 8. And then here's how we get batch for any arbitrary split. If the split is a training split, then we're going to look at train data, otherwise at val data. That gives us the data array. And then when I generate random positions to grab a chunk out of, I actually generate batch size number of random offsets. So because this is 4, Ix is going to be 4 numbers that are randomly generated between 0 and len of data minus block size. So it's just random offsets into the training set. And then x's, as I explained, are the first block size characters starting at i. The y's are offset by 1 of that. So just add plus 1. And then we're going to get those chunks for every one of integers i in ix. And use a torch.stack to take all those one-dimensional tensors, as we saw here. And we're going to stack them up as rows. And so they all become a row in a 4 by 8 tensor. So here's where I'm printing them. When I sample a batch xb and yb, the inputs of the transformer now are, the input x is the 4 by 8 tensor, four rows of eight columns. And each one of these is a chunk of the training set. And then the targets here are in the associated array y. And they will come into the transformer all the way at the end to create the loss function. So they will give us the correct answer for every single position inside x. And then these are the four independent rows. So spelled out, as we did before, this 4 by 8 array contains a total of 32 examples. And they're completely independent as far as the transformer is concerned. So when the input is 24, the target is 43. Or rather, 43 here in the y array. When the input is 24, 43, the target is 58. When the input is 24, 43, 58, the target is 5, etc. Or when it is a 5258, 1, the target is 58. Right, so you can see this spelled out. These are the 32 independent examples packed into a single batch of the input x. And then the desired targets are in y. And so now this integer tensor of x is going to feed into the transformer. And that transformer is going to simultaneously process all these examples and then look up the correct integers to predict in every one of these positions in the tensor y. Okay, so now that we have our batch of input that we'd like to feed into a transformer, let's start feeding this into neural networks. Now, we're going to start off with the simplest possible neural network, which, in the case of language modeling, in my opinion, is the bigram language model. And we've covered the bigram language model in my Make More series in a lot of depth. And so here I'm going to go faster and let's just implement the PyTorch module directly. That implements the bigram language model. So I'm importing the PyTorch NN module for reproducibility. And then here I'm constructing a bigram language model, which is a subclass of NN module. And then I'm calling it and I'm passing in the inputs and the targets. And I'm just printing. Now, when the inputs and targets come here, you see that I'm just taking the index, the inputs x here, which I renamed to idx. And I'm just passing them into this token embedding table. So what's going on here is that here in the constructor, we are creating a token embedding table. And it is of size, vocab size by vocab size. And we're using NN dot embedding, which is a very thin wrapper around a tensor of shape, vocab size by vocab size. And what's happening here is that when we pass idx here, every single integer in our input is going to refer to this embedding table and is going to pluck out a row of that embedding table corresponding to its index. So 24 here will go to the embedding table and we'll pluck out the 24th row. And then 43 will go here and pluck out the 43rd row, et cetera. And then PyTorch is going to arrange all of this into a batch by time by channel tensor. In this case, batch is 4, time is 8, and C, which is the channels, is vocab size, or 65. And so we're just going to pluck out all those rows, arrange them in a B by T by C, and now we're going to interpret this as the logits, which are the scores for the next character in the sequence. And so what's happening here is we are predicting what comes next based on just the individual identity of a single token. And you can do that because currently the tokens are not talking to each other and they're not seeing any context except that they're just seeing themselves. So I'm token number 5, and then I can actually make pretty decent predictions about what comes next just by knowing that I'm token 5 which are the scores for the next character in the sequence. And so what's happening here is we are predicting what comes next based on just the individual identity of a single token. And you can do that because currently the tokens are not talking to each other and they're not seeing any context except that they're just seeing themselves. So I'm token number 5, and then I can actually make pretty decent predictions about what comes next just by knowing that I'm token 5, because some characters follow other characters in typical scenarios. So we saw a lot of this in a lot more depth in the Make More series. And here, if I just run this, then we currently get the predictions, the scores, the logits for every one of the 4 by 8 positions. Now that we've made predictions about what comes next, we'd like to evaluate the loss function. And so in Make More series, we saw that a good way to measure a loss or a quality of the predictions is to use the negative log likelihood loss, which is also implemented in PyTorch under the name cross entropy. So what we'd like to do here is loss is the cross entropy on the predictions and the targets. And so this measures the quality of the logits with respect to the targets. In other words, we have the identity of the next character. So how well are we predicting the next character based on the logits? And intuitively, the correct dimension of logits, depending on whatever the target is, should have a very high number. And all the other dimensions should be a very low number, right? Now, the issue is that this won't actually, this is what we want. We want to output the logits and the loss. This is what we want, but unfortunately, this won't actually run. We get an error message. But intuitively, we want to measure this. Now, when we go to the PyTorch cross entropy documentation here, we're trying to call the cross entropy in its functional form. So that means we don't have to create a module for it. But here, when we go to the documentation, you have to look into the details of how PyTorch expects these inputs. And the issue here is PyTorch expects, if you have multi-dimensional input, which we do, because we have a B by T by C tensor, then it actually really wants the channels to be the second dimension here. So it wants a B by C by T instead of a B by T by C. And so it's just the details of how PyTorch treats these kinds of inputs. And so we don't actually want to deal with that. So what we're going to do instead is we need to reshape our logits. So here's what I like to do. I like to give names to the dimensions. So logits.shape is B by T by C, and unpack those numbers. And then let's say that logits equals logits.view. And we want it to be a B times T by C, so just a two-dimensional array. Right? So we're going to take all the, we're going to take all of these positions here, and we're going to stretch them out in a one-dimensional sequence and preserve the channel dimension as the second dimension. So we're just stretching out the array so it's two-dimensional. And in that case, it's going to better conform to what PyTorch expects in its dimensions. Now we have to do the same to targets because currently targets are of shape B by T, and we want it to be just B times T, so one-dimensional. Now, alternatively, you could always still just do minus one because PyTorch will guess what this should be if you want to lay it out. But let me just be explicit and say B times T. Once we've reshaped this, it will match the cross-entropy case, and then we should be able to evaluate our loss. Okay, so with that right now, and we can do loss. And so currently we see that the loss is 4.87. Now, because our, we have 65 possible vocabulary elements, we can actually guess at what the loss should be. And in particular, we covered negative log likelihood in a lot of detail. We are expecting log or lon of 1 over 65 and negative of that. So we're expecting the loss to be about 4.17, but we're getting 4.87. And so that's telling us that the initial predictions are not super diffuse. They've got a little bit of entropy. And so we're guessing wrong. So, yes. But actually we are able to evaluate the loss. we covered negative log likelihood in a lot of detail. We are expecting log or lon of 1 over 65 and negative of that. So we're expecting the loss to be about 4.17, but we're getting 4.87. And so that's telling us that the initial predictions are not super diffuse. They've got a little bit of entropy. And so we're guessing wrong. So, yes. But actually we are able to evaluate the loss. Okay, so now that we can evaluate the quality of the model on some data, we'd like to also be able to generate from the model. So let's do the generation. Now I'm going to go again a little bit faster here because I covered all this already in the previous videos. So here's a generate function for the model. So we take some, we take the same kind of input idx here. And this is the current context of some characters in a batch, in some batch. So it's also b by t. And the job of generate is to take this b by t and extend it to be b by t plus 1, plus 2, plus 3. And so it continues the generation in all the batch dimensions in the time dimension. So that's its job. And it will do that for max new tokens. So you can see here on the bottom, there's going to be some stuff here. But on the bottom, whatever is predicted is concatenated on top of the previous idx along the first dimension, which is the time dimension, to create a b by t plus 1. So that becomes the new idx. So the job of generate is to take a b by t and make it a b by t plus 1, plus 2, plus 3, as many as we want, max new tokens. So this is the generation from the model. Now, inside the generation, what are we doing? We're taking the current indices. We're getting the predictions. So we get those are in the logits. And then the loss here is going to be ignored because we're not using that, and we have no targets that are ground truth targets that we're going to be comparing with. Then once we get the logits, we are only focusing on the last step. So instead of a b by t by c, we're going to pluck out the negative one, the last element in the time dimension because those are the predictions for what comes next. So that gives us the logits, which we then convert to probabilities via softmax. And then we use torch.multinomial to sample from those probabilities. And we ask PyTorch to give us one sample. And so idx next will become a b by 1 because in each one of the batch dimensions, we're going to have a single prediction for what comes next. So this num samples equals 1 will make this be a 1. And then we're going to take those integers that come from the sampling process according to the probability distribution given here. And those integers just get concatenated on top of the current running stream of integers. And this gives us a b by t plus 1. And then we can return that. Now, one thing here is you see how I'm calling self of idx, which will end up going to the forward function. I'm not providing any targets. So currently, this would give an error because targets is not given. So targets has to be optional. So targets is none by default. And then if targets is none, then there's no loss to create. So it's just loss is none. But else, all of this happens and we can create a loss. So this will make it so if we have the targets, we provide them and get a loss. If we have no targets, we'll just get the logits. So this here will generate from the model. And let's take that for a ride now. Oops. So I have another code chunk here which will generate for the model, from the model. And okay, this is crazy. So maybe let me break this down. So these are the IDX, right? I'm creating a batch will be just one. Time will be just one. So I'm creating a little one by one tensor and it's holding a zero. And the dtype, the data type is integer. So zero is going to be how we kick off the generation. And remember that zero is the element standing for a newline character. So it's a reasonable thing to feed in as the very first character in a sequence to be the newline. So it's going to be IDX which we're going to feed in here. Then we're going to ask for 100 tokens. And then n.generate will continue that. Now because generate works on the level of batches, we then have to index into the zeroth row to unplug how we kick off the generation. And remember that zero is the element standing for a newline character. So it's a reasonable thing to feed in as the very first character in a sequence to be the newline. So it's going to be IDX, which we're going to feed in here. Then we're going to ask for 100 tokens. And then n.generate will continue that. Now, because generate works on the level of batches, we then have to index into the zeroth row to unplug the single batch dimension that exists. And then that gives us time steps, just a one-dimensional array of all the indices, which we will convert to a simple Python list from a PyTorch tensor so that that can feed into our decode function and convert those integers into text. So let me bring this back, and we're generating 100 tokens. Let's run. And here's the generation that we achieved. So obviously it's garbage. And the reason it's garbage is because this is a totally random model. So next up, we're going to want to train this model. Now one more thing I wanted to point out here is this function is written to be general, but it's ridiculous right now because we're feeding in all this, we're building out this context, and we're concatenating it all, and we're always feeding it all into the model. But that's ridiculous because this is just a simple bigram model. So to make, for example, this prediction about k, we only needed this w. But actually, what we fed into the model is we fed the entire sequence. And then we only looked at the very last piece and predicted k. So the only reason I'm writing it in this way is because right now this is a bigram model, but I'd like to keep this function fixed, and I'd like it to work later when our characters actually look further in the history. And so right now the history is not used, so this looks silly, but eventually the history will be used. And so that's why we want to do it this way. So just a quick comment on that. So now we see that this is random. So let's train the model so it becomes a bit less random. Okay, let's now train the model. So first what I'm going to do is I'm going to create a PyTorch optimization object. So here we are using the optimizer AdamW. Now in the Make More series, we've only ever used stochastic gradient descent, the simplest possible optimizer, which you can get using SGD instead. But I want to use Adam, which is a much more advanced and popular optimizer, and it works extremely well. For a typical good setting for the learning rate, it is roughly 3e-4. But for very, very small networks, like is the case here, you can get away with much, much higher learning rates, 1e-3 or even higher, probably. But let me create the optimizer object, which will take the gradients and update the parameters using the gradients. And then here, our batch size up above was only 4. So let me actually use something bigger, let's say 32. And then for some number of steps, we are sampling a new batch of data. We're evaluating the loss. We're zeroing out all the gradients from the previous step, getting the gradients for all the parameters, and then using those gradients to update our parameters. So, a typical training loop, as we saw in the Make More series. So let me now run this for, say, 100 iterations, and let's see what kind of losses we're going to get. So we started around 4.7, and now we're getting down to 4.6, 4.5, etc. So the optimization is definitely happening, but let's try to increase the number of iterations and only print at the end because we probably will train for longer. Okay, so we're down to 3.6 roughly. Roughly down to 3. This is the most janky optimization. Okay, it's working. Let's just do 10,000. And then from here, we want to copy this, and hopefully we're going to get something reasonable. And of course, it's not going to be Shakespeare from a bigram model, but at least we see that the loss is improving, and hopefully we're expecting something a bit more reasonable. Okay, so we're down at about 2.5-ish. Let's see what we get. Okay, dramatic improvement, certainly on what we had here. So let me just increase the number of tokens. Okay, so we see that we're starting to get something at least reasonable-ish. Certainly not Shakespeare, but the model is making progress. So that is the simplest possible model. So now what I'd like to do is, obviously, this is a very simple model because the tokens are not talking to each other. So given the previous context of whatever was generated, we're only looking at the very last character to make the predictions about what comes next. So now these tokens have to start talking to each other and figuring out what is in the context so that they can make better predictions for what comes next. And this is how we're going to kick off the transformer. Okay, so next, I took the code that we developed in this Jupyter notebook So now what I'd like to do is, obviously, this is a very simple model because the tokens are not talking to each other. So given the previous context of whatever was generated, we're only looking at the very last character to make the predictions about what comes next. So now these tokens have to start talking to each other and figuring out what is in the context so that they can make better predictions for what comes next. And this is how we're going to kick off the transformer. Okay, so next, I took the code that we developed in this Jupyter notebook and I converted it to be a script. And I'm doing this because I just want to simplify our intermediate work, which is just the final product that we have at this point. So at the top here, I put all the hyperparameters that we've defined. I introduced a few, and I'm going to speak to that in a little bit. Otherwise, a lot of this should be recognizable. Reproducibility, read data, get the encoder and the decoder, create the train and test splits, use the data loader that gets a batch of the inputs and targets. This is new, and I'll talk about it in a second. Now this is the bigram language model that we developed, and it can forward and give us logits and loss, and it can generate. And then here, we are creating the optimizer, and this is the training loop. So everything here should look pretty familiar. Now, some of the small things that I added: number one, I added the ability to run on a GPU if you have it. So if you have a GPU, then this will use CUDA instead of just CPU, and everything will be a lot faster. Now, when device becomes CUDA, then we need to make sure that when we load the data, we move it to device. When we create the model, we want to move the model parameters to device. So as an example, here we have the NN embedding table, and it's got a dot weight inside it, which stores the lookup table. So that would be moved to the GPU so that all the calculations here happen on the GPU, and they can be a lot faster. And then finally here, when I'm creating the context that feeds into generate, I have to make sure that I create on the device. Number two, what I introduced is the fact that here in the training loop, here I was just printing the loss dot item inside the training loop. But this is a very noisy measurement of the current loss because every batch will be more or less lucky. And so what I want to do usually is I have an estimate loss function, and the estimate loss then goes up here, and it averages up the loss over multiple batches. So in particular, we're going to iterate eval iter times, and we're going to get our loss, and then we're going to get the average loss for both splits. And so this will be a lot less noisy. So here when we call the estimate loss, we're going to report the pretty accurate train and validation loss. Now, when we come back up, you'll notice a few things here. I'm setting the model to evaluation phase, and down here, I'm resetting it back to training phase. Now, right now for our model as is, this doesn't actually do anything because the only thing inside this model is this nn.embedding, and this network would behave the same in both evaluation mode and training mode. We have no dropout layers, we have no batch norm layers, et cetera. But it is a good practice to think through what mode your neural network is in because some layers will have different behavior at inference time or training time. And there's also this context manager, torch.nograd. And this is just telling PyTorch that everything that happens inside this function, we will not call .backward on. And so PyTorch can be a lot more efficient with its memory use because it doesn't have to store all the intermediate variables because we're never going to call backward. And so it can be a lot more memory efficient in that way. So also a good practice to tell PyTorch when we don't intend to do backpropagation. So right now, this script is about 120 lines of code, and that's our starter code. I'm calling it bigram.py, and I'm going to release it later. Now running this script gives us output in the terminal, and it looks something like this. It, as I ran this code, it was giving me the train loss and the val loss, and we see that we converge to somewhere around 2.5 with the bigram model. And then here's the sample that we produced at the end. And so we have release it later. Now, running this script gives us output in the terminal, and it looks something like this. As I ran this code, it was giving me the train loss and the val loss, and we see that we convert to somewhere around 2.5 with the bigram model. And then here's the sample that we produced at the end. And so we have everything packaged up in the script, and we're in a good position now to iterate on this. Okay, so we are almost ready to start writing our very first self-attention block for processing these tokens. Now, before we actually get there, I want to get you used to a mathematical trick that is used in the self-attention inside a transformer and is really just at the heart of an efficient implementation of self-attention. And so I want to work with this toy example to get you used to this operation, and then it's going to make it much more clear once we actually get to it in the script again. So let's create a B by T by C, where B, T, and C are just 4, 8, and 2 in this toy example. And these are channels, and we have batches, and we have the time component, and we have some information at each point in the sequence. So C. Now, what we would like to do is we would like these tokens, so we have up to 8 tokens here in a batch, and these 8 tokens are currently not talking to each other, and we would like them to talk to each other. We'd like to couple them. And in particular, we want to couple them in a very specific way. So the token, for example, at the 5th location, it should not communicate with tokens in the 6th, 7th, and 8th location, because those are future tokens in the sequence. The token on the 5th location should only talk to the one in the 4th, 3rd, 2nd, and 1st. So it's only, so information only flows from previous context to the current time step, and we cannot get any information from the future because we are about to try to predict the future. So what is the easiest way for tokens to communicate? Okay. The easiest way, I would say, is, okay, if we're up to, if we're a 5th token and I'd like to communicate with my past, the simplest way we can do that is to just do a weight, is to just do an average of all the preceding elements. So, for example, if I'm the 5th token, I would like to take the channels that make up, that are information at my step, but then also the channels from the 4th step, 3rd step, 2nd step, and the 1st step. I'd like to average those up, and then that would become a feature vector that summarizes me in the context of my history. Now, of course, just doing a sum or an average is an extremely weak form of interaction. This communication is extremely lossy. We've lost a ton of information about the spatial arrangements of all those tokens, but that's okay for now. We'll see how we can bring that information back later. For now, what we would like to do is, for every single batch element independently, for every teeth token in that sequence, we'd like to now calculate the average of all the vectors in all the previous tokens and also at this token, so let's write that out. I have a small snippet here, and instead of just fumbling around, let me just copy paste it and talk to it. So, in other words, we're going to create X, and BOW is short for bag of words because bag of words is a term that people use when you are just averaging up things. So this is just a bag of words. There's a word stored on every one of these eight locations, and we're doing a bag of words for just averaging. So in the beginning, we're going to say that it's just initialized at zero, and then I'm doing a for loop here, so we're not being efficient yet. That's coming. But for now, we're just iterating a bag of words. There's a word stored on every one of these eight locations, and we're doing a bag of words for just averaging. So in the beginning, we're going to say that it's just initialized at zero, and then I'm doing a for loop here, so we're not being efficient yet. That's coming. But for now, we're just iterating over all the batch dimensions independently, iterating over time, and then the previous tokens are at this batch dimension, and then everything up to and including the teeth token. Okay? So when we slice out X in this way, Xprev becomes of shape, how many T elements there were in the past, and then, of course, C, so all the two-dimensional information from these little tokens. So that's the previous chunk of tokens from my current sequence, and then I'm just doing the average or the mean over the zero of dimensions, so I'm averaging out the time here, and I'm just going to get a little C one-dimensional vector, which I'm going to store in X bag of words. So I can run this, and this is not going to be very informative because, let's see, so this is X of zero, so this is the zeroth batch element, and then expo at zero. Now, you see how the at the first location here, you see that the two are equal, and that's because we're just doing an average of this one token. But here, this one is now an average of these two, and now this one is an average of these three, and so on. So, and this last one is the average of all of these elements, so vertical average, just averaging up all the tokens, now gives this outcome here. So, this is all well and good, but this is very inefficient. Now, the trick is that we can be very, very efficient about doing this using matrix multiplication. So, that's the mathematical trick, and let me show you what I mean. Let's work with a toy example here. Let me run it, and I'll explain. I have a simple matrix here that is a 3 by 3 of all ones, a matrix B of just random numbers, and it's a 3 by 2, and a matrix C, which will be 3 by 3 multiply 3 by 2, which will give out a 3 by 2. So, here we're just using matrix multiplication. So, A multiply B gives us C. Okay, so, how are these numbers in C achieved, right? So, this number in the top left is the first row of A dot product with the first column of B, and since all the row of A right now is all just ones, then the dot product here with this column of B is just going to do a sum of these, of this column. So, 2 plus 6 plus 6 is 14. The element here in the output of C is also the first column here, the first row of A multiplied now with the second column of B. So, 7 plus 4 plus 5 is 16. Now, you see that there's repeating elements here, so this 14 again is because this row is again all ones, and it's multiplying the first column of B, so we get 14, and this one is and so on. So, this last number here is the last row dot product, last column. Now, the trick here is the following. This is just a boring number of, it's just a boring array of all ones, but Torch has this function called trill, which is short for a triangular something like that, and you can wrap it in Torch.once, and it will just return the lower triangular portion of this. Okay, so now it will zero out these guys here, so we just get the lower triangular part. of, it's just a boring array of all ones, but Torch has this function called trill, which is short for a triangular something like that, and you can wrap it in Torch.once, and it will just return the lower triangular portion of this. Okay, so now it will zero out these guys here, so we just get the lower triangular part. Well, what happens if we do that? So, now we'll have A like this and B like this, and now what are we getting here in C? Well, what is this number? Well, this is the first row times the first column, and because this is zeros, these elements here are now ignored, so we just get a two. And then this number here is the first row times the second column, and because these are zeros, they get ignored, and it's just seven. The seven multiplies this one. But look what happened here. Because this is one and then zeros, what ended up happening is we're just plucking out this row of B, and that's what we got. Now here we have 110, so here 110.product with these two columns will now give us two plus six, which is eight, and seven plus four, which is eleven. And because this is one one one, we ended up with the addition of all of them. And so depending on how many ones and zeros we have here, we are doing a sum currently of the variable number of these rows, and that gets deposited into C. So currently we're doing sums because these are ones, but we can also do average, right? And you can start to see how we could do average of the rows of B in an incremental fashion, because we don't have to. We can normalize these rows so that they sum to one, and then we're going to get an average. So if we took A and then we did A equals A divide torch.sum in the of A in the one dimension, and then let's keep dim as true, so therefore the broadcasting will work out. So if I rerun this, you see now that these rows now sum to one. So this row is one, this row is 0.5.5 is zero, and here we get one third. And now when we do A multiply B, what are we getting? Here we are just getting the first row, first row. Here now we are getting the average of the first two rows. Okay, so two and six average is four, and four and seven average is 5.5. And on the bottom here we are now getting the average of these three rows. So the average of all of elements of B are now deposited here. And so you can see that by manipulating these elements of this multiplying matrix and then multiplying it with any given matrix, we can do these averages in this incremental fashion, because we just get and we can manipulate that based on the elements of A. Okay, so that's very convenient. So let's swing back up here and see how we can vectorize this and make it much more efficient using what we've learned. So in particular, we are going to produce an array A, but here I'm going to call it way, short for weights. But this is our A, and this is how much of every row we want to average up. And it's going to be an average because you can see that these rows sum to one. So this is our A, and then our B in this example, of course, is X. So what's going to happen here now is that we are going to have an X-bow 2, and this X-bow 2 is going to be way multiplying Rx. So let's think this through. way is T by T, and this is matrix multiplying in PyTorch, a B by T by C, and it's giving us what shape So what's going to happen here now is that we are going to have an X-bow 2, and this X-bow 2 is going to be way multiplying Rx. So let's think this through. Way is T by T, and this is matrix multiplying, in PyTorch, a B by T by C, and it's giving us what shape? So PyTorch will come here, and it will see that these shapes are not the same, so it will create a batch dimension here, and this is a batched matrix multiply. And so it will apply this matrix multiplication in all the batch elements, in parallel and individually. And then for each batch element, there will be a T by T multiplying T by C, exactly as we had below. So this will now create B by T by C, and X-bow 2 will now become identical to X-bow. So we can see that Torch.allclose of X-bow and X-bow 2 should be true now. So this convinces us that these are in fact the same. So X-bow and X-bow 2, if I just print them, okay, we're not going to be able to, okay, we're not going to be able to just stare it down, but let me try X-bow just at the zeroth element, and X-bow 2 at the zeroth element, so just the first batch, and we should see that this and that should be identical, which they are, right. So what happened here? The trick is we were able to use batched matrix multiply to do this aggregation, really, and it's a weighted aggregation. And the weights are specified in this T by T array, and we're doing weighted sums, and these weighted sums are according to the weights inside here that take on this triangular form. And so that means that a token at the t dimension will only get information from the tokens preceding it. So that's exactly what we want. And finally, I would like to rewrite it in one more way, and we're going to see why that's useful. So this is the third version, and it's also identical to the first and second, but let me talk through it. It uses softmax. So trill here is this matrix: lower triangular ones. Way begins as all zero. Okay, so if I just print way in the beginning, it's all zero. Then I used masked fill. So what this is doing is weight dot masked fill. It's all zeros, and I'm saying, for all the elements where trill is equal to equal zero, make them be negative infinity. So all the elements where trill is zero will become negative infinity now. So this is what we get. And then the final line here is softmax. So if I take a softmax along every single, so dim is negative one, so along every single row, if I do a softmax, what is that going to do? Well, softmax is also a normalization operation, right? And so, spoiler alert, you get the exact same matrix. Let me bring back the softmax and recall that in softmax, we're going to exponentiate every single one of these, and then we're going to divide by the sum. And so if we exponentiate every single element here, we're going to get a one, and here we're going matrix. Let me bring back the softmax and recall that in softmax, we're going to exponentiate every single one of these, and then we're going to divide by the sum. If we exponentiate every single element here, we're going to get a one, and here we're going to get zero, zero, zero, zero, zero everywhere else. Then, when we normalize, we just get one here. Here, we're going to get one, one, and then zeros, and then softmax will again divide, and this will give us 0.5, 0.5, and so on. This is also the same way to produce this mask. Now, the reason that this is a bit more interesting, and the reason we're going to end up using it in self-attention, is that these weights here begin with zero, and you can think of this as an interaction strength or an affinity. It's telling us how much of each token from the past do we want to aggregate and average up. This line is saying tokens from the past cannot communicate. By setting them to negative infinity, we're saying that we will not aggregate anything from those tokens. This then goes through softmax and through the weighted aggregation through matrix multiplication. What this is now is, you can think of these zeros as currently just set by us to be zero, but a quick preview is that these affinities between the tokens are not going to be just constant at zero. They're going to be data-dependent. These tokens are going to start looking at each other, and some tokens will find other tokens more or less interesting, and depending on what their values are, they're going to find each other interesting to different amounts. I'm going to call those affinities, I think. Here, we are saying the future cannot communicate with the past. We're going to clamp them, and then when we normalize and sum, we're going to aggregate their values depending on how interesting they find each other. That's the preview for self-attention. Long story short, from this entire section, you can do weighted aggregations of your past elements by using matrix multiplication in a lower triangular fashion. The elements here in the lower triangular part are telling you how much of each element fuses into this position. We're going to use this trick now to develop the self-attention block. of a lower triangular fashion, and then the elements here in the lower triangular part are telling you how much of each element fuses into this position. So we're going to use this trick now to develop the self attention block. So first, let's get some quick preliminaries out of the way. First, the thing I'm bothered by is that you see how we're passing in vocab size into the constructor. There's no need to do that because vocab size is already defined up top as a global variable. So there's no need to pass this stuff around. Next, what I want to do is, I don't want to actually create, I want to create a level of indirection here, where we don't directly go to the embedding for the logits, but instead we go through this intermediate phase because we're going to start making that bigger. So let me introduce a new variable, n embed. It's short for number of embedding dimensions. So n embed here will be, say, 32. That was a suggestion from GitHub Copilot, by the way. It also suggests 32, which is a good number. So this is an embedding table and only 32 dimensional embeddings. So then here, this is not going to give us logits directly. Instead, this is going to give us token embeddings. That's what I'm going to call it. And then to go from the token embeddings to the logits, we're going to need a linear layer. So self.lm head, let's call it, short for language modeling head, is n linear from n embed up to vocab size. And then when we swing over here, we're actually going to get the logits by exactly what the Copilot says. Now we have to be careful here because this c and this c are not equal. This is n embed c, and this is vocab size. So let's just say that n embed is equal to c, and then this just creates one spurious layer of indirection through a linear layer, but this should run. So we see that this runs, and this currently looks spurious. creates one spurious layer of indirection through a linear layer, but this should run, so we see that this runs, and this currently looks spurious, but we're going to build on top of this now. Next up, so far we've taken these indices and we've encoded them based on the identity of the tokens inside idx. The next thing that people very often do is that we're not just encoding the identity of these tokens, but also their position. So we're going to have a second position embedding table here. So self.position_embedding_table is an embedding of block size by an embed, and so each position from 0 to block size minus one will also get its own embedding vector. And then here, first let me decode b by t from idx.shape, and then here we're also going to have a pos_embedding, which is the positional embedding, and this is tordach arrange. So this will be just integers from 0 to t minus 1, and all of those integers from 0 to t minus 1 get embedded through the table to create a t by c. And then here this gets renamed to just say x, and x will be the addition of the token embeddings with the positional embeddings. And here the broadcasting node will work out, so b by t by c plus t by c. This gets right aligned, a new dimension of one gets added, and it gets broadcasted across batch. So at this point x holds not just the token identities, but the positions at which these tokens occur, and this is currently not that useful because, of course, we just Point x holds not just the token identities, but the positions at which these tokens occur, and this is currently not that useful because, of course, we just have a simple bigray model, so it doesn't matter if you're in the fifth position, the second position, or wherever. It's all translation invariant at this stage, so this information currently wouldn't help. But as we work on the self-attention block, we'll see that this starts to matter. Okay, so now we get the crux of self-attention. This is probably the most important part of this video to understand. We're going to implement a small self-attention for a single individual head, as they're called. So right now, I'm working with an example where I change the number of channels from 2 to 32, so we have a 4x8 arrangement of tokens, and the information at each token is currently 32 dimensional. But we are working with random numbers. Now, we saw here that the code as we had before does a simple average of all the past tokens and the current token, so the previous information and current information is being mixed together in an average, and that's what this code currently achieves. And it does so by creating this lower triangular structure, which allows us to mask out this way matrix that we create. So we mask it out, and then we normalize it. And currently, when we initialize the affinities between all the different tokens, or nodes, I'm going to use those terms interchangeably, so when we initialize the affinities between all the different tokens to be zero, then we see that way gives us this structure where every single row has So, when we initialize the affinities between all the different tokens to be zero, then we see that way gives us this structure where every single row has these uniform numbers, and so that's what then, in this matrix multiply, makes it so that we're doing a simple average. Now, we don't actually want this to be all uniform because different tokens will find different other tokens more or less interesting, and we want that to be data dependent. So, for example, if I'm a vowel, then maybe I'm looking for consonants in my past, and maybe I want to know what those consonants are, and I want that information to flow to me. And so I want to now gather information from the past, but I want to do it in a data-dependent way, and this is the problem that self-attention solves. Now, the way self-attention solves this is the following: every single node, or every single token at each position, will emit two vectors. It will emit a query, and it will emit a key. Now, the query vector, roughly speaking, is "what am I looking for," and the key vector, roughly speaking, is "what do I contain." And then the way we get affinities between these tokens now in a sequence is we just do a dot product between the keys and the queries. So my query dot products with all the keys of all the other tokens, and that dot product now becomes way. And so if the key and the query are aligned, they will interact to a very high amount, and then I will get to learn more about that specific token, as opposed to any other token in the sequence. So let's implement this now. We're going to implement a single what's called head of self-attention. So this is just one head. There's a hyperparameter involved with these heads, which is the head. going to implement a single what's called head of self attention so this is just one head there's a hyperparameter involved with these heads which is the head size and then here I'm initializing linear modules and I'm using bias equals false so these are just going to apply matrix multiply with some fixed weights and now let me produce a k and q by forwarding these modules on x so the size of this will now become b by t by 16 because that is the head size and the same here b by t by 16 so this being the head size so you see here that when I forward this linear on top of my x all the tokens in all the positions in the b by t arrangement all of them in parallel and independently produce a key and a query so no communication has happened yet but the communication comes now all the queries will dot product with all the keys so what we want is we want way now or the affinities between these to be the query multiplying key but we have to be careful with we can't matrix multiply this we actually need to transpose k but we have to be also careful because these are when you have the batch dimension so in particular we want to transpose the last two dimensions dimension negative one and dimension negative two so negative two negative one and so this matrix multiply now will do the following b by t by 16 matrix multiplies b by 16 by t to give us b by t by t right so for every row of b we're now going to have a Matrix multiplies b by 16 by t to give us b by t by t, right? So for every row of b, we're now going to have a t square matrix giving us the affinities, and these are now the way. So they're not zeros; they are now coming from this dot product between the keys and the queries. So this can now run. I can run this, and the weighted aggregation now is a function in a data manner between the keys and queries of these nodes. So just inspecting what happened here, the way takes on this form, and you see that before, way was just a constant, so it was applied in the same way to all the batch elements. But now every single batch elements will have different way because every single batch element contains different tokens at different positions, and so this is not data dependent. So when we look at just the zeroth row, for example, in the input, these are the weights that came out. And so you can see now that they're not just exactly uniform, and in particular, as an example here, for the last row, this was the eighth token, and the eighth token knows what content it has, and it knows what position it's in, and now the eighth token, based on that, creates a query: hey, I'm looking for this kind of stuff. I'm a vowel. I'm looking for any consonants at positions up to four. And then all the nodes get to emit keys, and maybe one of the channels could be, I am a consonant, and I am in a position up to four, and that key would have a high and maybe one of the channels could be, I am a consonant, and I am in a position up to four, and that key would have a high affinity. When they have a high affinity, say this token was pretty interesting to this eighth token, when they have a high affinity, then through the softmax, I will end up aggregating a lot of its information into my position, and so I'll get to learn a lot about it. now, we're looking at this way after this has already happened. Let me erase this operation as well, so let me erase the masking and the softmax, just to show you the under-the-hood internals and how that works. so without the masking and the softmax, way comes out like this, right? This is the output of the dot products, and these are the raw outputs, and they take on values from negative 2 to positive 2, etc. So that's the raw interactions and raw affinities between all the nodes. but actually, we use the upper triangular masking, so those are not allowed to communicate, and now we actually want to have a nice distribution, so we don't want to aggregate negative 0.11 of this node. That's crazy. So instead, we exponentiate and normalize, and now we get a nice distribution that sums to 1, and this is telling us now, in a data-dependent manner, how much information to aggregate from any of these tokens in the past. So that's way, and it's not zeros anymore, but it's calculated in this way. now there's one more part to a single self-attention head, and that is that when we do It's not zeros anymore, but it's calculated in this way now. There's one more part to a single self-attention head, and that is that when we do the aggregation, we don't actually aggregate the tokens exactly. We aggregate, we produce one more value here, and we call that the value. In the same way that we produced key, query, and then here, we don't aggregate x. We calculate a v, which is just achieved by propagating this linear on top of x again, and then we output way multiplied by v. So v is the elements that we aggregate, or the vector that we aggregate, instead of the raw x. And now, of course, this will make it so that the output here of the single head will be 16-dimensional because that is the head size. So you can think of x as private information to this token, if you think about it that way. So x is private to this token. So I'm a fifth token, and I have some identity, and my information is kept in vector x. And now, for the purposes of the single head, here's what I'm interested in, here's what I have, and if you find me interesting, here's what I will communicate to you, and that's stored in V. And so V is the thing that gets aggregated for the purposes of this single head between the different nodes, and that's the self-attention mechanism. This is what it does. There are a few notes that I would like to make about attention. Number one: attention is a communication mechanism. You can really think about it as a communication mechanism where you have a number of nodes in a directed graph. would like to make about attention. Number one, attention is a communication mechanism. You can really think about it as a communication mechanism where you have a number of nodes in a directed graph, where you have edges pointing between nodes, this and what happens is every node has some vector of information, and it gets to aggregate information via a weighted sum from all nodes that point to it. This is done in a data-dependent manner, so depending on whatever data is actually stored at each node at any point in time. Now our block size is 8, and there's always 8 tokens, and the first node is only pointed to by itself. The second node is pointed to by the first node and itself, all the way up to the eighth node, which is pointed to by all the previous nodes and itself. That's the structure that our directed graph has, or happens to have, in an autoregressive scenario like language modeling. But in principle, attention can be applied to any arbitrary directed graph, and it's just a communication mechanism between the nodes. The second node is that there is no notion of space, so attention simply acts over a set of vectors in this graph, and so by default these nodes have no idea where they are positioned in the space, and that's why we need to encode them positionally and give them some information that is anchored to a specific position so that they know where they are. This is different than, for example, from convolution because if you run, for example, a convolution operation over some input, there is a very specific layout of the information in space. than, for example, from convolution, because if you run, for example, a convolution operation over some input, there is a very specific layout of the information in space, and the convolutional filters act in space. And so it's not inattention. Inattention is just a set of vectors out there in space. They communicate, and if you want them to have a notion of space, you need to specifically add it, which is what we done when we calculated the positional encodings and added that information to the vectors. The next thing that I hope is very clear is that the elements across the batch dimension never talk to each other. They're always processed independently, and this is a batch matrix multiply that applies a matrix multiplication in parallel across the batch dimension. So maybe it would be more accurate to say that in this analogy of a directed graph, we really have four separate pools of eight nodes, and those eight nodes only talk to each other. But in total, there's 32 nodes that are being processed, but there's four separate pools of eight. You can look at that way. The next note is that here, in the case of language modeling, we have this specific structure of directed graph where the future tokens will not communicate to the past tokens. But this doesn't necessarily have to be the constraint in the general case, and in fact, in many cases you may want to have all the nodes talk to each other fully. So, as an example, if you're doing sentiment analysis or something that with are predicting, for example, the sentiment of the sentence, and so it's okay so, as an example, if you're doing sentiment analysis or something that with are predicting, for example, the sentiment of the sentence, and so it's okay for these nodes to talk to each other, and so in those cases you will use an encoder block of self-attention, and all it means that it's an encoder block is that you will delete this line of code, allowing all the nodes to completely talk to each other. what we're implementing here is sometimes called a decoder block, and it's called a decoder because it is like decoding language, and it's got this autoregressive format where you have to mask with the triangular matrix so that nodes from the future never talk to the past because they would give away the answer, and so in encoder blocks you would delete this, allow all the nodes to talk. In decoder blocks this will always be present so that you have this triangular structure, but both are allowed, and attention doesn't care. Attention supports arbitrary connectivity between nodes. The next thing I wanted to comment on is, you keep me, you keep hearing me say attention, self-attention, etc. There's actually also something called cross-attention. What is the difference? So the reason this attention is self-attention is because the keys, queries, and the values are all coming from the same source, from x. So the same source x produces keys, queries, and values, so these nodes are self-attending. But in principle, attention is much more general than that. So, for example, in encoder-decoder transformers, you can have a case where the queries are produced from x, but the keys and the values come from a whole separate external source, and sometimes from encoder blocks that encode some context that we'd like to condition on, and so the keys and the values will actually come from a whole separate source. Those are nodes on the side, and here we're just producing queries, and we're reading off information from the side. So cross-attention is used when there's a separate source of nodes we'd like to pull information from into our nodes, and it's self-attention if we just have nodes that would like to look at each other and talk to each other. So this attention here happens to be self-attention, but in principle attention is a lot more general. Okay, and the last note at this stage is, if we come to the Attention Is All You Need paper here, we've already implemented attention, so given query, key, and value, we've multiplied the query on the key, we've softmaxed it, and then we are aggregating the values. There's one more thing that we're missing here, which is the dividing by one over square root of the head size. The dk here is the head size. Why aren't they doing this? Why is this important? So they call it scaled attention, and it's an important normalization to have. The problem is, if you have unit Gaussian inputs, so zero mean, unit variance, k and q are unit Gaussian, then if you just do wA naively, then you see that your wA actually will be, the variance will be on the order of head size, which in our case is 16. But if you multiply by one over head size square root, so this is square root and this is one over, then the variance of wA will be one, so it will be preserved. Now, why is this important? You'll notice that wA here will feed into softmax, and so it's really important, especially at initialization, that wA be fairly diffuse. So in our case here, we locked out here, and wA had fairly diffuse numbers here, so this now. The problem is that because of softmax, if weight takes on very positive and very negative numbers inside it, softmax will actually converge towards one- hot vectors, and so I can illustrate that here. Say we are applying softmax to a tensor of values that are very close to zero, then we're going to get a diffuse thing out of softmax. But the moment I take the exact same thing and I start sharpening it and making it bigger by multiplying these numbers by eight, for example, you'll see that the softmax will start to sharpen, and in fact it will sharpen towards the max, so it will sharpen towards whatever number here is the highest. And so we don't want these values to be too extreme, especially at initialization, otherwise softmax will be way too peaky, and you're aggregating information from a single node. Every node just aggregates information from a single other node. That's not what we want, especially at initialization, and so the scaling is used just to control the variance at initialization. Okay, so having said all that, let's now take our self-attention knowledge and take it for a spin. So here in the code I've created this head module and implements a single head of self-attention. So you give it a head size, and then here it creates the key, query, and the value linear layers. Typically people don't use biases in these, so those are the linear projections that we're going to apply to all of our nodes. Now here I'm creating this tril variable. tril is not a parameter of the module, so in pytorch naming conventions this is called a buffer. It's not a parameter, and you have to call it, you have to assign it to the module using a register buffer. So that creates the tril, the lower triangular matrix, and when we're given the input x, this should look very familiar. Now we calculate the keys, the queries, we call it calculate the attention scores inside wA, we normalize it, so we're using scaled attention here, then we make sure that a feature doesn't communicate with the past, so this makes it a decoder block, and then softmax, and then aggregate the value and output. Then here in the language model I'm creating a head in the constructor, and I'm calling it self-attention head, and the head size I'm going to keep as the same and embed just for now. And then here, once we've encoded the information with the token embeddings and the position register buffer, so that creates the tril, the trying lower triangular matrix, and when we're given the input x this should look very familiar now. We calculate the keys, the queries, we call it calculate the attention scores. Inside, we normalize it, so we're using scaled attention here. Then we make sure that a feature doesn't communicate with the past, so this makes it a decoder block, and then softmax, and then aggregate the value and output. Then here in the language model, I'm creating a head in the constructor and I'm calling it self-attention head, and the head size I'm going to keep as the same and embed just for now. And then here, once we've encoded the information with the token embeddings and the position embeddings, we're simply going to feed it into the self-attention head, and then the output of that is going to go into the decoder language modeling head and create the logits. So this is the simplest way to plug in a self-attention component into our network right now. I had to make one more change, which is that here in the generate, we have to make sure that our idx that we feed into the model, because now we're using positional embeddings, we can never have more than block size coming in, because if idx is more than block size, then our position embedding table is going to run out of scope because it only has embeddings for up to block size. And so therefore, I added some code here to crop the context that we're going to feed into self so that we never pass in more than block size elements. So those are the changes, and let's now train the network. Okay, so I also came up to the script here, and I decreased the learning rate because the self-attention can't tolerate very, very high learning rates, and then I also increased number of iterations because the learning rate is lower. And then I trained it, and previously we were only able to get to up to 2.5, and now we are down to 2.4. So we definitely see a little bit of improvement from 2.5 to 2.4, roughly, but the text is still not amazing. So clearly the self-attention head is doing some useful communication, but we still have a long way to go. Okay, so now we've implemented the scale.product attention. Now next up in the Attention Is All You Need paper, there's something called multi-head attention. And what is multi-head attention? It's just applying multiple attentions in parallel and concatenating the results. So they have a little bit of diagram here. I don't know if this is super clear. It's really just multiple attentions in parallel. So let's implement that, fairly straightforward. If we want a multi-head attention, then we want multiple heads of self-attention running in parallel. So in PyTorch, we can do this by simply creating multiple heads, so however many heads you want, and then what is the head size of each. And then we run all of them in parallel into a list and simply concatenate all of the outlets. And we're concatenating over the channel dimension. So the way this looks now is we don't have just a single attention that has a head size of 32, because remember an embed is 32. Instead of having one communication channel, we now have four communication channels in parallel, and each one of these communication channels typically will be smaller correspondingly. So because we have four communication channels, we want eight-dimensional self-attention, and so from each communication channel we're getting together eight-dimensional vectors, and then we have four of them, and that concatenates to give us 32, which is the original and embed. And so this is similar to if you're familiar with convolutions. This is like a group convolution because instead of having one large convolution, we do convolution in groups, and that's multi-headed self-attention. And so then here we just use sa heads, self-attention heads, instead. Now I actually ran it, and scrolling down, I ran the same thing, and then we now get down to 2.28, roughly, and the output is still, the generation is still not amazing, but clearly the validation loss is improving because we were at 2.4 just now. And so it helps to have multiple communication channels because obviously these tokens have a lot to talk about. They want to find the consonants, the vowels. They want to find the vowels just from certain positions. They want to find any kinds of different things, and so it helps to create multiple independent channels of communication, gather lots of different types of data, and then decode the output. Now going back to the paper for a second, of course I didn't explain this figure in full detail, but we are starting to see some components of what we've already implemented. We have the positional encodings, the token encodings that add. We have the masked multi-headed attention implemented now. Here's another multi-headed attention, which is a cross attention to an encoder, which we haven't, we're not going to implement in this case. I'm going to come back to that later, but I want you to notice that there's a feed forward part here, and then this is grouped into a block that gets repeated again and again. Now the feed forward part here is just a simple multi-layer perceptron. So the multi-headed, so here position wise feed forward networks is just a simple little mlp. So I want to start in a similar fashion, also adding computation into the network, and this computation is on a per node level. So I've already implemented it, and you can see the diff highlighted on the left here when I've added or changed things now. Before, we had the multi-headed self-attention that did the communication, but we went way too fast to calculate the logits, so the tokens looked at each other but didn't really have a lot of time to think on what they found from the other tokens. And so what I've implemented here is a little feed forward single layer, and this little layer is just a linear followed by a relu non-linearity, and that's it. So it's just a little layer, and then I call it feed forward and embed, and then this feed forward is just called sequentially right after the self-attention. So we self-attend, then we feed forward. And you'll notice that the feed forward here, when it's applying linear, this is on a per token level. All the tokens do this independently. So the self-attention is the communication, and then once they've gathered all the data, now they need to think on that data individually, and so that's what feed forward is doing, and that's why I've added it here. Now when I train this, the validation loss actually continues to go down, now to 2.24, which is down from 2.28. The output still look terrible, but at least we've improved the situation. And so as a preview, we're going to now start to intersperse the communication with the computation, and that's also what the transformer does when it has blocks that communicate and then compute, and it groups them and replicates them. Okay, so let me show you what we'd like to do. We'd like to do something like this. We have a block, and this block is this part here except for the cross attention. Now the block intersperses communication and then computation. The computation, the communication is done using multi-headed self-attention, and then the computation is done using a feed forward network, and all the tokens independently. Now what I've added here also is you'll notice this takes the number of embeddings in the embedding dimension and the number of heads that we would like, which is like group sizing, group convolution, and I'm saying that number of heads we'd like is four. And so because this is 32, we calculate that because this is 32, the number of heads should be four, number, the head size should be eight so that everything works out channel wise. We have a block, and this block is this part here, except for the cross attention. Now, the block intersperses communication and then computation. The communication is done using multi-headed self-attention, and then the computation is done using a feed-forward network on all the tokens independently. Now, what I've added here also is you'll notice this takes the number of embeddings in the embedding dimension and the number of heads that we would like, which is group sizing, group convolution, and I'm saying that number of heads we'd like is four. Because this is 32, we calculate that the number of heads should be four. The head size should be eight so that everything works out channel-wise. This is how the transformer structures the sizes typically, so the head size will become eight, and this is how we want to intersperse them. Then here, I'm trying to create blocks, which is just a sequential application of block, block, block, so that we're interspersing communication and feed-forward many, many times, and then finally we decode. Now, I actually tried to run this, and the problem is this doesn't actually give a very good answer and very good result, and the reason for that is we're starting to actually get a pretty deep neural net, and deep neural nets suffer from optimization issues, and I think that's what we're slightly starting to run into. So we need one more idea that we can borrow from the transformer paper to resolve those difficulties. Now, there are two optimizations that dramatically help with the depth of these networks and make sure that the networks remain optimizable. Let's talk about the first one. The first one in this diagram is you see this arrow here, and then this arrow and this arrow. Those are skip connections, or sometimes called residual connections. They come from this paper, the procedural learning for image recognition, from about 2015, that introduced the concept. Now, these are what it means: you transform the data, but then you have a skip connection with addition from the previous features. Now, the way I like to visualize it, that I prefer, is the following. Here, the computation happens from the top to bottom, and you have this residual pathway, and you are free to fork off from the residual pathway, perform some computation, and then project back to the residual pathway via addition. So you go from the inputs to the targets only through plus and plus and plus, and the reason this is useful is because during that propagation, remember from our micrograd video earlier, addition distributes gradients equally to both of its branches that fed us the input, and so the supervision or the gradients from the loss hop through every addition node all the way to the input and then also fork off into the residual blocks, but you have this gradient superhighway that goes directly from the supervision all the way to the input unimpeded. Then these original blocks are usually initialized in the beginning so they contribute very, very little, if anything, to the residual pathway. They are initialized that way, so in the beginning they are almost not there, but then during the optimization they come online over time and they start to contribute. But at least at the initialization, you can go directly from supervision to the input. Gradient is unimpeded and just flows, and then the blocks over time kick in, and so that dramatically helps with the optimization. So let's implement this. Coming back to our block here, what we want to do is we want to do x equals x plus self-attention and x equals x plus self.feedforward. So this is x, and then we fork off and do some communication and come back, and we fork off and we do some computation and come back. So those are residual connections, and then swinging back up here, we also have to introduce this projection, so nn.linear, and this is going to be from after we concatenate this. This is the size n embed, so this is the output of the self-attention itself, but then we actually want to apply the projection, and that's the result. So the projection is just a linear transformation of the outcome of this layer, so that's the projection back into the residual pathway. Then here in the feedforward, it's going to be the same thing. I could have a self-taught projection here as well, but let me just simplify it and let me couple it inside the same sequential container. So this is the projection layer going back into the residual pathway, and so that's it. So now we can train this. I implemented one more small change. When you look into the paper again, you see that the dimensionality of input and output is 512 for them, and they're saying that the inner layer here in the feedforward has dimensionality of 2048, so there's a multiplier of four. So the inner layer of the feedforward network should be multiplied by four in terms of channel sizes. So I came here and I multiplied four times embed here for the feedforward, and then from four times n embed, coming back down to n embed when we go back to the projection. So adding a bit of computation here and growing that layer that is in the residual block on the side of the residual pathway, and then I train this, and we actually get down all the way to 2.08 validation loss. We also see that the network is starting to get big enough that our train loss is getting ahead of validation loss, so we start to see a little bit of overfitting, and our generations here are still not amazing, but at least you see that we can see this now grief sank. This starts to almost look like English, so yeah, we're starting to really get there. Okay, and the second innovation that is very helpful for optimizing very deep neural networks is right here. So we have this addition. Now, that's the residual part, but this norm is referring to something called layer norm. So layer norm is implemented in pytorch. It's a paper that came out a while back, and layer norm is very, very similar to bash norm. So remember back to our make more series part three, we implemented bash normalization, and bash normalization just made sure that across the bash dimension, any individual neuron had unit gaussian distribution, so it was zero mean and unit standard deviation, one standard deviation output. So what I did here is I'm copy-pasting the bash norm 1d that we developed in our make more series, and see here we can initialize, for example, this module, and we can have a batch of 32 100-dimensional vectors feeding through the bash norm layer. So what this does is it guarantees that when we look at just the zeroth column, it's a zero mean, one standard deviation, so it's normalizing every single column of this input. Now, the rows are not going to be normalized by default because we're just normalizing columns. So let's now implement layer norm. It's very complicated. Look, we come here, we change this from zero to one, so we don't normalize the columns, we normalize the rows, and now we've implemented layer norm. So now the columns are not going to be normalized, but the rows are going to be normalized. For every individual example, its 100-dimensional vector is normalized in this way, and because our computation now does not span across examples, we can delete all of this buffers stuff because we can always apply this operation and don't need to maintain any running buffers. So we don't need the buffers. There's no distinction between training and test time. And we don't need these running buffers. We do keep gamma and beta. We don't need the momentum. Look, we come here, we change this from zero to one, so we don't normalize the columns, we normalize the rows. And now we've implemented layer norm, so now the columns are not going to be normalized. But the rows are going to be normalized for every individual example. Its 100 dimensional vector is normalized in this way, and because our computation now does not span across examples, we can delete all of this buffers stuff because we can always apply this operation and don't need to maintain any running buffers, so we don't need the buffers. There's no distinction between training and test time, and we don't need these running buffers. We do keep gamma and beta. We don't need the momentum. We don't care if it's training or not, and this is now a layer norm, and it normalizes the rows instead of the columns, and this here is identical to this here, so let's now implement layer norm in our transformer. Before I incorporate the layer norm, I just wanted to note that, as I said, very few details about the transformer have changed in the last five years, but this is actually something that likely departs from the original paper. You see that the add and norm is applied after the transformation, but now it is a bit more common to apply the layer norm before the transformation, so there's a reshuffling of the layer norms. So this is called the pre-norm formulation, and that's the one that we're going to implement as well, so slight deviation from the original paper. We need two new layer norms. Layer norm one is an nn.LayerNorm, and we tell it how many, what is the embedding dimension, and we need the second layer norm. And then here, the layer norms are applied immediately on x, so self.layer_norm1 applied on x and self.layer_norm2 applied on x before it goes into self-attention and feedforward, and the size of the layer norm here is n_embed, so 32. So when the layer norm is normalizing our features, the normalization here happens, the mean and the variance are taken over 32 numbers, so the batch and the time act as batch dimensions, both of them, so this is a per-token transformation that just normalizes the features and makes them a unit mean, unit Gaussian at initialization, but of course because these layer norms inside it have these gamma and beta trainable parameters, the layer norm will eventually create outputs that might not be unit Gaussian, but the optimization will determine that. So for now, this is incorporating the layer norms, and let's train them up. Okay, so I let it run, and we see that we get down to 2.06, which is better than the previous 2.08, so a slight improvement by adding the layer norms, and I'd expect that they help even more if we had a bigger and deeper network. One more thing I forgot to add is that there should be a layer norm here also, typically at the end of the transformer and right before the final linear layer that decodes into vocabulary, so I added that as well. So at this stage, we actually have a pretty complete transformer according to the original paper, and it's a decoder-only transformer. I'll talk about that in a second, but at this stage the major pieces are in place, so we can try to scale this up and see how well we can push this number. Now in order to scale out the model, I had to perform some cosmetic changes here to make it nicer, so I introduced this variable called n_layer, which just specifies how many layers of the blocks we're going to have. I create a bunch of blocks, and we have a new variable, number of heads, as well. I pulled out the layer norm here, and so this is identical now. One thing that I did briefly change is I added dropout, so dropout is something that you can add right before the residual connection back, right before the connection back into the residual pathway, so we can drop out that as the last layer here. We can drop out here at the end of the multi-headed restriction as well, and we can also drop out here when we calculate the affinities, and after the softmax we can drop out some of those, so we can randomly prevent some of the nodes from communicating. And so dropout comes from this paper from 2014 or so, and it takes your neural net and it randomly, every forward backward pass, shuts off some subset of neurons, so randomly drops them to zero and trains without them. And what this does effectively is because the mask of what's being dropped out has changed every single forward backward pass, it ends up training an ensemble of subnetworks, and then at test time everything is fully enabled, and all of those subnetworks are merged into a single ensemble, if you want to think about it that way. So I would read the paper to get the full detail. For now, we're just going to stay on the level of this is a regularization technique, and I added it because I'm about to scale up the model quite a bit, and I was concerned about overfitting. So now when we scroll up to the top, we'll see that I changed a number of hyperparameters here about our neural net, so I made the batch size be much larger now, 64. I changed the block size to be 256, so previously it was just eight, eight characters of context. Now it is 256 characters of context to predict the 257th. I brought down the learning rate a little bit because the neural net is now much bigger, so I brought down the learning rate. The embedding dimension is now 384, and there are six heads, so 384 divide six means that every head is 64 dimensional, as a standard, and then there are going to be six layers of that, and the dropout will be a 0.2. So every forward backward pass, 20 of all these intermediate calculations are disabled and dropped to zero, and then I already trained this and I ran it, so drum roll, how well does it perform? So let me just scroll up here. We get a validation loss of 1.48, which is actually quite a bit of an improvement on what we had before, which I think was 2.07, so we went from 2.07 all the way down to 1.48 just by scaling up this neural net with the code that we have, and this of course ran for a lot longer. This may be trained for, I want to say, about 15 minutes on my A100 GPU, so that's a pretty good GPU, and if you don't have a GPU, you're not going to be able to reproduce this on a CPU. This would be, I would not run this on the CPU or a MacBook or something like that. You'll have to break down the number of layers and the embedding dimension and so on, but in about 15 minutes we can get this kind of a result, and I'm printing some of the Shakespeare here, but what I did also is I printed 10,000 characters, so a lot more, and I wrote them to a file, and so here we see some of the outputs. So it's a lot more recognizable as the input text file. So the input text file, just for reference, looked like this, so there's always someone speaking in this manner, and our predictions now take on that form, except of course they're nonsensical when you actually read them, so it is every crimty be a house oh those prepation we give heed oh ho sent me you mighty lord Anyway, so you can read through this. It's nonsensical, of course, but this is just a transformer trained on the character level for one million characters that come from Shakespeare 10,000 characters, so a lot more, and I wrote them to a file, and so here we see some of the outputs. So it's a lot more recognizable as the input text file. So the input text file, just for reference, looks like this, so there's always someone speaking in this manner, and our predictions now take on that form, except, of course, they're nonsensical when you actually read them. It is every crimty be a house oh those prepation we give heed. Oh ho sent me you mighty lord. Anyway, so you can read through this. It's nonsensical, of course, but this is just a transformer trained on the character level for one million characters that come from Shakespeare, so it blabbers on in Shakespeare-like manner, but it doesn't, of course, make sense at this scale, but I think still a pretty good demonstration of what's possible. So now I think that concludes the programming section of this video. We did a pretty good job of implementing this transformer, but the picture doesn't exactly match up to what we've done, so what's going on with all these additional parts here? So let me finish explaining this architecture and why it looks so funky. What's happening here is what we implemented here is a decoder-only transformer, so there's no component here. This part is called the encoder, and there's no cross-attention block here. Our block only has a self-attention and the feed- forward, so it is missing this third in-between piece here. This piece does cross-attention, so we don't have it, and we don't have the encoder. We just have the decoder, and the reason we have a decoder-only is because we are just generating text, and it's unconditioned on anything. We're just blabbering on according to a given data set. What makes it a decoder is that we are using the triangular mask in our transformer, so it has this autoregressive property where we can just go and sample from it. So the fact that it's using the triangular mask to mask out the attention makes it a decoder, and it can be used for language modeling. Now, the reason that the original paper had an encoder-decoder architecture is because it is a machine translation paper, so it is concerned with a different setting. In particular, it expects some tokens that encode, say, for example, French, and then it is expected to decode the translation in English. So you typically, these here are special tokens, so you are expected to read in this and condition on it, and then you start off the generation with a special token called start. So this is a special new token that you introduce and always place in the beginning, and then the network is expected to output neural networks are awesome, and then a special end token to finish the generation. So this part here will be decoded exactly as we've done it. Neural networks are awesome will be identical to what we did, but unlike what we did, they want to condition the generation on some additional information, and in that case, this additional information is the French sentence that they should be translating. So what they do now is they bring the encoder. Now the encoder reads this part here, so we're only going to take the part of French, and we're going to create tokens from it exactly as we've seen in our video, and we're going to put a transformer on it, but there's going to be no triangular mask, and so all the tokens are allowed to talk to each other as much as they want, and they're just encoding whatever's the content of this French sentence. Once they've encoded it, they basically come out in the top here, and then what happens here is in our decoder, which does the language modeling, there's an additional connection here to the outputs of the encoder, and that is brought in through a cross-attention. So the queries are still generated from x, but now the keys and the values are coming from the side. The keys and the values are coming from the top, generated by the nodes that came out of the encoder, and those top keys and values feed in on the side into every single block of the decoder, and so that's why there's an additional cross-attention, and really what it's doing is it's conditioning the decoding not just on the past of this current decoding, but also on having seen the fully encoded French prompt, and so it's an encoder-decoder model, which is why we have those two transformers and an additional block and so on. So we did not do this because we have nothing to encode. There's no conditioning. We just have a text file, and we just want to imitate it, and that's why we are using a decoder-only transformer exactly as done in GPT. Okay, so now I wanted to do a very brief walkthrough of nanoGPT, which you can find on my GitHub, and nanoGPT is two files of interest. There's train.py and model.py. train.py is all the boilerplate code for training the network. It is basically all the stuff that we had here. It's the training loop. It's just that it's a lot more complicated because we're saving and loading checkpoints and pre-trained weights, and we are decaying the learning rate and compiling the model and using distributed training across multiple nodes or GPUs, so the training.py gets a little bit more hairy and complicated. There's more options, etc., but the model.py should look very, very similar to what we've done here. In fact, the model is almost identical. So first here we have the causal self-attention block, and all of this should look very, very recognizable to you. We're producing queries, keys, values, we're doing dot products, we're masking, applying softmax, optionally dropping out, and here we are pooling the values. What is different here is that in our code, I have separated out the multi-headed attention into just a single individual head, and then here I have multiple heads, and I explicitly concatenate them, whereas here all of it is implemented in a batched manner inside a single causal self-attention, and so we don't just have a b and a t and a c dimension. We also end up with a fourth dimension, which is the heads, and so it just gets a lot more hairy because we have four-dimensional array tensors now, but it is equivalent mathematically, so the exact same thing is happening as what we have. It's just a bit more efficient because all the heads are now treated as a batch dimension as well. Then we have the multilayer perceptron. It's using the GELU non-linearity, which is defined here, except instead of ReLU, and this is done just because OpenAI used it, and I want to be able to load their checkpoints. The blocks of the transformer are identical, the communicate and the compute phase as we saw, and then the GPT will be identical. We have the position encodings, token encodings, the blocks, the layer norm at the end, the final linear layer, and this should all look very recognizable, and there's a bit more here because I'm loading checkpoints and stuff like that. I'm separating out the parameters into those that should be weight decayed and those that shouldn't, but the generate function should also be very, very similar. So a few details are different, but you should definitely be able to look at this file and be able to understand a lot of the pieces now. So let's now bring things back to ChatGPT. What would it look like if we wanted to train ChatGPT ourselves, and how does it relate to what we learned today? Well, to train ChatGPT, there are roughly two stages. First is the pre-training stage and then the fine-tuning stage. In the pre-training This should look very recognizable, and there's a bit more here because I'm loading checkpoints and stuff like that. I'm separating out the parameters into those that should be weight decayed and those that shouldn't, but the generate function should also be very, very similar, so a few details are different, but you should definitely be able to look at this file and be able to understand a lot of the pieces now. So let's now bring things back to ChatGPT. What would it look like if we wanted to train ChatGPT ourselves, and how does it relate to what we learned today? Well, to train ChatGPT, there are roughly two stages. First is the pre-training stage, and then the fine-tuning stage. In the pre-training stage, we are training on a large chunk of internet and just trying to get a first decoder-only transformer to babble text, so it's very, very similar to what we've done ourselves, except we've done a tiny little baby pre-training step. In our case, this is how you print a number of parameters. I printed it, and it's about 10 million, so this transformer that I created here to create a little Shakespeare transformer was about 10 million parameters. Our data set is roughly one million characters, so roughly one million tokens, but you have to remember that OpenAI uses different vocabulary. They're not on the character level. They use these subword chunks of words, and so they have a vocabulary of 50,000 roughly elements, and so their sequences are a bit more condensed, so our data set, the Shakespeare data set, would be probably around 300,000 tokens in the OpenAI vocabulary, roughly. So we trained about a 10 million parameter model on roughly 300,000 tokens. Now, when you go to the GPT-3 paper and you look at the transformers that they trained, they trained a number of transformers of different sizes, but the biggest transformer here has 175 billion parameters, so ours is, again, 10 million. They used this number of layers in the transformer. This is the n embed, this is the number of heads, and this is the head size. Then this is the batch size, so ours was 65, and the learning rate is similar. Now, when they trained this transformer, they trained on 300 billion tokens, so again, remember ours is about 300,000, so this is about a million-fold increase, and this number would not be even that large by today's standards. You'd be going up one trillion and above, so they are training a significantly larger model on a good chunk of the internet, and that is the pre-training stage, but otherwise these hyperparameters should be fairly recognizable to you, and the architecture is actually nearly identical to what we implemented ourselves. But, of course, it's a massive infrastructure challenge to train this. You're talking about typically thousands of GPUs having to talk to each other to train models of this size, so that's just the pre-training stage. Now, after you complete the pre-training stage, you don't get something that responds to your questions with answers, and it's not helpful, etc. You get a document completer, right? So it babbles, but it doesn't babble Shakespeare, it babbles internet. It will create arbitrary news articles and documents, and it will try to complete documents because that's what it's trained for. It's trying to complete the sequence, so when you give it a question, it would potentially just give you more questions. It would follow with more questions. It will do whatever it looks like some close document would do in the training data on the internet, and so who knows? You're getting undefined behavior. It might answer questions with other questions. It might ignore your question. It might just try to complete some news article. It's totally unaligned, as we say, so the second fine-tuning stage is to actually align it to be an assistant, and this is the second stage. This ChatGPT blog post from OpenAI talks a little bit about how this stage is achieved. There's roughly three steps to this stage, so what they do here is they start to collect training data that looks specifically like what an assistant would do, so they are documents that have the format where the question is on top and then an answer is below, and they have a large number of these, but probably not on the order of the internet. This is probably on the order of maybe thousands of examples, and so they then fine-tune the model to focus on documents that look like that, and so you're starting to slowly align it, so it's going to expect a question at the top, and it's going to expect to complete the answer, and these very, very large models are very sample efficient during their fine-tuning, so this actually somehow works, but that's just step one. That's just fine-tuning. Then they actually have more steps where, okay, the second step is you let the model respond, and then different raters look at the different responses and rank them for their preference as to which one is better than the other. They use that to train the reward model so they can predict, using a different network, how much any candidate response would be desirable, and then once they have a reward model, they run PPO, which is a form of policy gradient reinforcement learning optimizer, to fine-tune this sampling policy so that the answers that GPT, ChatGPT now generates are expected to score a high reward according to the reward model, and so there's a whole aligning stage here, or fine-tuning stage. It's got multiple steps in between there as well, and it takes the model from being a document completer to a question answerer, and that's a whole separate stage. A lot of this data is not available publicly. It is internal to OpenAI, and it's much harder to replicate this stage. So that's roughly what would give you a ChatGPT, and nanoGPT focuses on the pre-training stage, okay? That's everything that I wanted to cover today. So we trained, to summarize, a decoder-only transformer following this famous paper, Attention Is All You Need, from 2017, and that's basically a GPT. We trained it on Tiny Shakespeare and got sensible results. All of the training code is roughly 200 lines of code. I will be releasing this code base, so also it comes with all the git log commits along the way as we built it up. In addition to this code, I'm going to release the notebook, of course, the Google Colab, and I hope that gave you a sense for how you can train these models, like, say, GPT-3, that will be architecturally identical to what we have, but they are somewhere between 10,000 and 1 million times bigger, depending on how you count, and so that's all I have for now. We did not talk about any of the fine- tuning stages that would typically go on top of this, so if you're interested in something that's not just language modeling, but you actually want to perform tasks, or you want them to be aligned in a specific way, or you want to detect sentiment, or anything like that, basically, anytime you don't want something that's just a document completer, you have to complete further stages of fine-tuning, which we did not cover, and that could be simple supervised fine-tuning, or it can be something more fancy like we see in ChatGPT. We actually train a reward model and then do runs of PPO to align it with respect to the reward model, so there's a lot more that can be done on top of it. I think, for now, we're starting to get to about the two-hour mark, so I'm going to finish here. I hope you enjoyed the lecture, and yeah, go forth and transform. See you later. and it does so by creating this lower triangular structure which allows us to mask out this way matrix that we create so we mask it out and then we normalize it and currently when we initialize the affinities between all the different tokens or nodes I'm going to use those terms interchangeably so when we initialize the affinities between all the different tokens to be zero then we see that way gives us this structure where every single row has these uniform numbers and so that's what then in this matrix multiply makes it so that we're doing a simple average now we don't actually want this to be all uniform because different tokens will find different other tokens more or less interesting and we want that to be data dependent so for example if I'm a vowel then maybe I'm looking for consonants in my past and maybe I want to know what those consonants are and I want that information to flow to me and so I want to now gather information from the past but I want to do it in a data dependent way and this is the problem that self-attention solves now the way self-attention solves this is the following every single node or every single token at each position will emit two vectors it will emit a query and it will emit a key now the query vector roughly speaking is what am I looking for and the key vector roughly speaking is what do I contain and then the way we get affinities between these tokens now in a sequence is we basically just do a dot product between the keys and the queries so my query dot products with all the keys of all the other tokens and that dot product now becomes way and so if the key and the query are sort of aligned they will interact to a very high amount and then I will get to learn more about that specific token as opposed to any other token in the sequence so let's implement this now we're going to implement a single what's called head of self attention so this is just one head there's a hyperparameter involved with these heads which is the head size and then here I'm initializing linear modules and I'm using bias equals false so these are just going to apply matrix multiply with some fixed weights and now let me produce a k and q by forwarding these modules on x so the size of this will now become b by t by 16 because that is the head size and the same here b by t by 16 so this being the head size so you see here that when I forward this linear on top of my x all the tokens in all the positions in the b by t arrangement all of them in parallel and independently produce a key and a query so no communication has happened yet but the communication comes now all the queries will dot product with all the keys so basically what we want is we want way now or the affinities between these to be the query multiplying key but we have to be careful with we can't matrix multiply this we actually need to transpose k but we have to be also careful because these are when you have the batch dimension so in particular we want to transpose the last two dimensions dimension negative one and dimension negative two so negative two negative one and so this matrix multiply now will basically do the following b by t by 16 matrix multiplies b by 16 by t to give us b by t by t right so for every row of b we're now going to have a t square matrix giving us the affinities and these are now the way so they're not zeros they are now coming from this dot product between the keys and the queries so this can now run I can run this and the weighted aggregation now is a function in a data manner between the keys and queries of these nodes so just inspecting what happened here the way takes on this form and you see that before way was just a constant so it was applied in the same way to all the batch elements but now every single batch elements will have different sort of way because every single batch element contains different tokens at different positions and so this is not data dependent so when we look at just the zeroth row for example in the input these are the weights that came out and so you can see now that they're not just exactly uniform and in particular as an example here for the last row this was the eighth token and the eighth token knows what content it has and it knows what position it's in and now the eighth token based on that creates a query hey I'm looking for this kind of stuff I'm a vowel I'm looking for any consonants at positions up to four and then all the nodes get to emit keys and maybe one of the channels could be I am a consonant and I am in a position up to four and that key would have a high affinity and when they have a high affinity like say this token was pretty interesting to this eighth token when they have a high affinity then through the softmax I will end up aggregating a lot of its information into my position and so I'll get to learn a lot about it now just this we're looking at way after this has already happened let me erase this operation as well so let me erase the masking and the softmax just to show you the under the hood internals and how that works so without the masking and the softmax way comes out like this right this is the outputs of the dot products and these are the raw outputs and they take on values from negative 2 to positive 2 etc so that's the raw interactions and raw affinities between all the nodes but so actually we use the upper triangular masking so those are not allowed to communicate and now we actually want to have a nice distribution so we don't want to aggregate negative 0.11 of this node that's crazy so instead we exponentiate and normalize and now we get a nice distribution that sums to 1 and this is telling us now in a data dependent manner how much information to aggregate from any of these tokens in the past so that's way and it's not zeros anymore but it's calculated in this way now there's one more part to a single self attention head and that is that when we do the aggregation we don't actually aggregate the tokens exactly we aggregate we produce one more value here and we call that the value so in the same way that we produced key query and then here we don't aggregate x we calculate a v which is just achieved by propagating this linear on top of x again and then we output way multiplied by v so v is the elements that we aggregate or the vector that we aggregate instead of the raw x and now of course this will make it so that the output here of the single head will be 16 dimensional because that is the head size so you can think of x as kind of like private information to this token if you think about it that way so x is kind of private to this token so I'm a fifth token and I have some identity and my information is kept in vector x and now for the purposes of the single head here's what I'm interested in here's what I have and if you find me interesting here's what I will communicate to you and that's stored in V and so V is the thing that gets aggregated for the purposes of this single head between the different nodes and that's basically the self-attention mechanism this is what it does there are a few notes that I would like to make about attention number one attention is a communication mechanism you can really think about it as a communication mechanism where you have a number of nodes in a directed graph where basically you have edges pointing between nodes like this and what happens is every node has some vector of information and it gets to aggregate information via a weighted sum from all nodes that point to it and this is done in a data dependent manner so depending on whatever data is actually stored at each node at any point in time now our block size is 8 and there's always 8 tokens and the first node is only pointed to by itself the second node is pointed to by the first node and itself all the way up to the eighth node which is pointed to by all the previous nodes and itself and so that's the structure that our directed graph has or happens to have in an autoregressive scenario like language modeling but in principle attention can be applied to any arbitrary directed graph and it's just a communication mechanism between the nodes the second node is that there is no notion of space so attention simply acts over a set of vectors in this graph and so by default these nodes have no idea where they are positioned in the space and that's why we need to encode them positionally and sort of give them some information that is anchored to a specific position so that they know where they are and this is different than for example from convolution because if you run for example a convolution operation over some input there is a very specific layout of the information in space and the convolutional filters act in space and so it's not like inattention inattention is just a set of vectors out there in space they communicate and if you want them to have a notion of space you need to specifically add it which is what we done when we calculated the positional encodings and added that information to the vectors the next thing that I hope is very clear is that the elements across the batch dimension never talk to each other they're always processed independently and this is a batch matrix multiply that applies basically a matrix multiplication in parallel across the batch dimension so maybe it would be more accurate to say that in this analogy of a directed graph we really have four separate pools of eight nodes and those eight nodes only talk to each other but in total there's like 32 nodes that are being processed but there's sort of four separate pools of eight you can look at that way the next note is that here in the case of language modeling we have this specific structure of directed graph where the future tokens will not communicate to the past tokens but this doesn't necessarily have to be the constraint in the general case and in fact in many cases you may want to have all the nodes talk to each other fully so as an example if you're doing sentiment analysis or something like that with are predicting for example the sentiment of the sentence and so it's okay for these nodes to talk to each other and so in those cases you will use an encoder block of self attention and all it means that it's an encoder block is that you will delete this line of code allowing all the nodes to completely talk to each other what we're implementing here is sometimes called a decoder block and it's called a decoder because it is sort of like a decoding language and it's got this autoregressive format where you have to mask with the triangular matrix so that nodes from the future never talk to the past because they would give away the answer and so basically in encoder blocks you would delete this allow all the nodes to talk in decoder blocks this will always be present so that you have this triangular structure but both are allowed and attention doesn't care attention supports arbitrary connectivity between nodes the next thing i wanted to comment on is you keep me you keep hearing me say attention self-attention etc there's actually also something called cross-attention what is the difference so basically the reason this attention is self-attention is because the keys queries and the values are all coming from the same source from x so the same source x produces keys queries and values so these nodes are self-attending but in principle attention is much more general than that so for example in encoder decoder transformers you can have a case where the queries are produced from x but the keys and the values come from a whole separate external source and sometimes from encoder blocks that encode some context that we'd like to condition on and so the keys and the values will actually come from a whole separate source those are nodes on the side and here we're just producing queries and we're reading off information from the side so cross-attention is used when there's a separate source of nodes we'd like to pull information from into our nodes and it's self-attention if we just have nodes that would like to look at each other and talk to each other so this attention here happens to be self-attention but in principle attention is a lot more general okay and the last note at this stage is if we come to the attention is all you need paper here we've already implemented attention so given query key and value we've multiplied the query on the key we've soft maxed it and then we are aggregating the values there's one more thing that we're missing here which is the dividing by one over square root of the head size the dk here is the head size why aren't they doing this why is this important so they call it a scaled attention and it's kind of like an important normalization to basically have the problem is if you have unit gaussian inputs so zero mean unit variance k and q are unit gaussian then if you just do way naively then you see that your way actually will be the variance will be on the order of head size which in our case is 16 but if you multiply by one over head size square root so this is square root and this is one over then the variance of way will be one so it will be preserved now why is this important you'll notice that way here will feed into softmax and so it's really important especially at initialization that way be fairly diffuse so in our case here we sort of locked out here and way had a fairly diffuse numbers here so um like this now the problem is that because of softmax if weight takes on very positive and very negative numbers inside it softmax will actually converge towards one hot vectors and so i can illustrate that here um say we are applying softmax to a tensor of values that are very close to zero then we're going to get a diffuse thing out of softmax but the moment i take the exact same thing and i start sharpening it and making it bigger by multiplying these numbers by eight for example you'll see that the softmax will start to sharpen and in fact it will sharpen towards the max so it will sharpen towards whatever number here is the highest and so um basically we don't want these values to be too extreme especially at initialization otherwise softmax will be way too peaky and um you're basically aggregating um information from like a single node every node just aggregates information from a single other node that's not what we want especially at initialization and so the scaling is used just to control the variance at initialization okay so having said all that let's now take our self-attention knowledge and let's take it for a spin so here in the code i've created this head module and implements a single head of self-attention so you give it a head size and then here it creates the key query and the value linear layers typically people don't use biases in these so those are the linear projections that we're going to apply to all of our nodes now here i'm creating this trill variable trill is not a parameter of the module so in sort of pytorch naming conventions this is called a buffer it's not a parameter and you have to call it you have to assign it to the module using a register buffer so that creates the trill the trying lower triangular matrix and when we're given the input x this should look very familiar now we calculate the keys the queries we call it calculate the attention scores inside way we normalize it so we're using scaled attention here then we make sure that a feature doesn't communicate with the past so this makes it a decoder block and then softmax and then aggregate the value and output then here in the language model i'm creating a head in the constructor and i'm calling it self-attention head and the head size i'm going to keep as the same and embed just for now and then here once we've encoded the information with the token embeddings and the position embeddings we're simply going to feed it into the self-attention head and then the output of that is going to go into the decoder language modeling head and create the logits so this is sort of the simplest way to plug in a self-attention component into our network right now i had to make one more change which is that here in the generate we have to make sure that our idx that we feed into the model because now we're using positional embeddings we can never have more than block size coming in because if idx is more than block size then our position embedding table is going to run out of scope because it only has embeddings for up to block size and so therefore i added some code here to crop the context that we're going to feed into self so that we never pass in more than block size elements so those are the changes and let's now train the network okay so i also came up to the script here and i decreased the learning rate because the self-attention can't tolerate very very high learning rates and then i also increased number of iterations because the learning rate is lower and then i trained it and previously we were only able to get to up to 2.5 and now we are down to 2.4 so we definitely see a little bit of improvement from 2.5 to 2.4 roughly but the text is still not amazing so clearly the self-attention head is doing some useful communication but we still have a long way to go okay so now we've implemented the scale.product attention now next up in the attention is all you need paper there's something called multi-head attention and what is multi-head attention it's just applying multiple attentions in parallel and concatenating the results so they have a little bit of diagram here i don't know if this is super clear it's really just multiple attentions in parallel so let's implement that fairly straightforward if we want a multi-head attention then we want multiple heads of self-attention running in parallel so in pytorch we can do this by simply creating multiple heads so however many heads you want and then what is the head size of each and then we run all of them in parallel into a list and simply concatenate all of the outlets and we're concatenating over the channel dimension so the way this looks now is we don't have just a single attention that has a head size of 32 because remember an embed is 32 instead of having one communication channel we now have four communication channels in parallel and each one of these communication channels typically will be smaller correspondingly so because we have four communication channels we want eight-dimensional self-attention and so from each communication channel we're getting together eight-dimensional vectors and then we have four of them and that concatenates to give us 32 which is the original and embed and so this is kind of similar to if you're familiar with convolutions this is kind of like a group convolution because basically instead of having one large convolution we do convolution in groups and that's multi-headed self-attention and so then here we just use sa heads self-attention heads instead now i actually ran it and scrolling down i ran the same thing and then we now get down to 2.28 roughly and the output is still the generation is still not amazing but clearly the validation loss is improving because we were at 2.4 just now and so it helps to have multiple communication channels because obviously these tokens have a lot to talk about they want to find the consonants the vowels they want to find the vowels just from certain positions they want to find any kinds of different things and so it helps to create multiple independent channels of communication gather lots of different types of data and then decode the output now going back to the paper for a second of course i didn't explain this figure in full detail but we are starting to see some components of what we've already implemented we have the positional encodings the token encodings that add we have the masked multi-headed attention implemented now here's another multi-headed attention which is a cross attention to an encoder which we haven't we're not going to implement in this case i'm going to come back to that later but i want you to notice that there's a feed forward part here and then this is grouped into a block that gets repeated again and again now the feed forward part here is just a simple multi-layer perceptron so the multi-headed so here position wise feed forward networks is just a simple little mlp so i want to start basically in a similar fashion also adding computation into the network and this computation is on a per node level so i've already implemented it and you can see the diff highlighted on the left here when i've added or changed things now before we had the multi-headed self-attention that did the communication but we went way too fast to calculate the logits so the tokens looked at each other but didn't really have a lot of time to think on what they found from the other tokens and so what i've implemented here is a little feed forward single layer and this little layer is just a linear followed by a relu non-linearity and that's that's it so it's just a little layer and then i call it feed forward and embed and then this feed forward is just called sequentially right after the self-attention so we self-attend then we feed forward and you'll notice that the feed forward here when it's applying linear this is on a per token level all the tokens do this independently so the self-attention is the communication and then once they've gathered all the data now they need to think on that data individually and so that's what feed forward is doing and that's why i've added it here now when i train this the validation loss actually continues to go down now to 2.24 which is down from 2.28 the output still look kind of terrible but at least we've improved the situation and so as a preview we're going to now start to intersperse the communication with the computation and that's also what the transformer does when it has blocks that communicate and then compute and it groups them and replicates them okay so let me show you what we'd like to do we'd like to do something like this we have a block and this block is basically this part here except for the cross attention now the block basically intersperses communication and then computation the computation the communication is done using multi-headed self-attention and then the computation is done using a feed forward network and all the tokens independently now what i've added here also is you'll notice this takes the number of embeddings in the embedding dimension and the number of heads that we would like which is kind of like group sizing group convolution and i'm saying that number of heads we'd like is four and so because this is 32 we calculate that because this is 32 the number of heads should be four um number the head size should be eight so that everything sort of works out channel wise um so this is how the transformer structures uh sort of the uh the sizes typically so the head size will become eight and then this is how we want to intersperse them and then here i'm trying to create blocks which is just a sequential application of block block block so that we're interspersing communication feed forward many many times and then finally we decode now i actually tried to run this and the problem is this doesn't actually give a very good uh answer and very good result and the reason for that is we're starting to actually get like a pretty deep neural net and deep neural nets uh suffer from optimization issues and i think that's what we're kind of like slightly starting to run into so we need one more idea that we can borrow from the transformer paper to resolve those difficulties now there are two optimizations that dramatically help with the depth of these networks and make sure that the networks remain optimizable let's talk about the first one the first one in this diagram is you see this arrow here and then this arrow and this arrow those are skip connections or sometimes called residual connections they come from this paper uh the procedural learning for image recognition from about 2015 uh that introduced the concept now these are basically what it means is you transform the data but then you have a skip connection with addition from the previous features now the way i like to visualize it uh that i prefer is the following here the computation happens from the top to bottom and basically you have this uh residual pathway and you are free to fork off from the residual pathway perform some computation and then project back to the residual pathway via addition and so you go from the the inputs to the targets only the plus and plus and plus and the reason this is useful is because during that propagation remember from our micrograd video earlier addition distributes gradients equally to both of its branches that that fed us the input and so the supervision or the gradients from the loss basically hop through every addition node all the way to the input and then also fork off into the residual blocks but basically you have this gradient superhighway that goes directly from the supervision all the way to the input unimpeded and then these original blocks are usually initialized in the beginning so they contribute very very little if anything to the residual pathway they they are initialized that way so in the beginning they are almost kind of like not there but then during the optimization they come online over time and they start to contribute but at least at the initialization you can go from directly supervision to the input gradient is unimpeded and just flows and then the blocks over time kick in and so that dramatically helps with the optimization so let's implement this so coming back to our block here basically what we want to do is we want to do x equals x plus self-attention and x equals x plus self.feedforward so this is x and then we fork off and do some communication and come back and we fork off and we do some computation and come back so those are residual connections and then swinging back up here we also have to introduce this projection so nn.linear and this is going to be from after we concatenate this this is the size n embed so this is the output of the self-attention itself but then we actually want the uh to apply the projection and that's the result so the projection is just a linear transformation of the outcome of this layer so that's the projection back into the residual pathway and then here in the feedforward it's going to be the same thing i could have a self-taught projection here as well but let me just simplify it and let me uh couple it inside the same sequential container and so this is the projection layer going back into the residual pathway and so that's uh well that's it so now we can train this so i implemented one more small change when you look into the paper again you see that the dimensionality of input and output is 512 for them and they're saying that the inner layer here in the feedforward has dimensionality of 2048 so there's a multiplier of four and so the inner layer of the feedforward network should be multiplied by four in terms of channel sizes so i came here and i multiplied four times embed here for the feedforward and then from four times n embed coming back down to n embed when we go back to the project to the projection so adding a bit of computation here and growing that layer that is in the residual block on the side of the residual pathway and then i train this and we actually get down all the way to uh 2.08 validation loss and we also see that the network is starting to get big enough that our train loss is getting ahead of validation loss so we start to see like a little bit of overfitting and um our our um generations here are still not amazing but at least you see that we can see like is here this now grief sank like this starts to almost look like english so um yeah we're starting to really get there okay and the second innovation that is very helpful for optimizing very deep neural networks is right here so we have this addition now that's the residual part but this norm is referring to something called layer norm so layer norm is implemented in pytorch it's a paper that came out a while back here um and layer norm is very very similar to bash norm so remember back to our make more series part three we implemented bash normalization and uh bash normalization basically just made sure that um across the bash dimension any individual neuron had unit uh gaussian um distribution so it was zero mean and unit standard deviation one standard deviation output so what i did here is i'm copy pasting the bash norm 1d that we developed in our make more series and see here we can initialize for example this module and we can have a batch of 32 100 dimensional vectors feeding through the bash norm layer so what this does is it guarantees that when we look at just the zeroth column it's a zero mean one standard deviation so it's normalizing every single column of this uh input now the rows are not uh going to be normalized by default because we're just normalizing columns so let's now implement layer norm uh it's very complicated look we come here we change this from zero to one so we don't normalize the columns we normalize the rows and now we've implemented layer norm so now the columns are not going to be normalized but the rows are going to be normalized for every individual example it's 100 dimensional vector is normalized uh in this way and because our computation now does not span across examples we can delete all of this buffers stuff because we can always apply this operation and don't need to maintain any running buffers so we don't need the buffers uh we don't there's no distinction between training and test time uh and we don't need these running buffers we do keep gamma and beta we don't need the momentum we don't care if it's training or not and this is now a layer norm and it normalizes the rows instead of the columns and this here is identical to basically this here so let's now implement layer norm in our transformer before i incorporate the layer norm i just wanted to note that as i said very few details about the transformer have changed in the last five years but this is actually something that's likely departs from the original paper you see that the add and norm is applied after the transformation but um in now it is a bit more basically common to apply the layer norm before the transformation so there's a reshuffling of the layer norms so this is called the pre-norm formulation and that's the one that we're going to implement as well so slight deviation from the original paper basically we need two new layer norms layer norm one is uh an end dot layer norm and we tell it how many um what is the embedding dimension and we need the second layer norm and then here the layer norms are applied immediately on x so self dot layer norm one applied on x and self dot layer norm two applied on x before it goes into self-attention and feedforward and the size of the layer norm here is an embed so 32 so when the layer norm is normalizing our features it is the normalization here happens the mean and the variance are taken over 32 numbers so the batch and the time act as batch dimensions both of them so this is kind of like a per token um transformation that just normalizes the features and makes them a unit mean uh unit gaussian at initialization but of course because these layer norms inside it have these gamma and beta trainable parameters the layer norm will eventually create outputs that might not be unit gaussian but the optimization will determine that so for now this is the uh this is incorporating the layer norms and let's train them up okay so i let it run and we see that we get down to 2.06 which is better than the previous 2.08 so a slight improvement by adding the layer norms and i'd expect that they help uh even more if we had bigger and deeper network one more thing i forgot to add is that there should be a layer norm here also typically as at the end of the transformer and right before the final linear layer that decodes into vocabulary so i added that as well so at this stage we actually have a pretty complete uh transformer according to the original paper and it's a decoder only transformer i'll i'll talk about that in a second but at this stage the major pieces are in place so we can try to scale this up and see how well we can push this number now in order to scale out the model i had to perform some cosmetic changes here to make it nicer so i introduced this variable called n layer which just specifies how many layers of the blocks we're going to have i create a bunch of blocks and we have a new variable number of heads as well i pulled out the layer norm here and so this is identical now one thing that i did briefly change is i added dropout so dropout is something that you can add right before the residual connection back right before the connection back into the residual pathway so we can drop out that as the last layer here we can drop out uh here at the end of the multi-headed restriction as well and we can also drop out here uh when we calculate the um basically affinities and after the softmax we can drop out some of those so we can randomly prevent some of the nodes from communicating and so dropout uh comes from this paper from 2014 or so and basically it takes your neural nut and it randomly every forward backward pass shuts off some subset of uh neurons so randomly drops them to zero and trains without them and what this does effectively is because the mask of what's being dropped out has changed every single forward backward pass it ends up kind of uh training an ensemble of sub networks and then at test time everything is fully enabled and kind of all of those sub networks are merged into a single ensemble if you can if you want to think about it that way so i would read the paper to get the full detail for now we're just going to stay on the level of this is a regularization technique and i added it because i'm about to scale up the model quite a bit and i was concerned about overfitting so now when we scroll up to the top we'll see that i changed a number of hyper parameters here about our neural net so i made the batch size be much larger now 64. i changed the block size to be 256 so previously it was just eight eight characters of context now it is 256 characters of context to predict the 257th uh i brought down the learning rate a little bit because the neural net is now much bigger so i brought down the learning rate the embedding dimension is now 384 and there are six heads so 384 divide six means that every head is 64 dimensional as it as a standard and then there are going to be six layers of that and the dropout will be a 0.2 so every forward backward pass 20 of all these um intermediate calculations are disabled and dropped to zero and then i already trained this and i ran it so uh drum roll how well does it perform so let me just scroll up here we get a validation loss of 1.48 which is actually quite a bit of an improvement on what we had before which i think was 2.07 so we went from 2.07 all the way down to 1.48 just by scaling up this neural net with the code that we have and this of course ran for a lot longer this may be trained for i want to say about 15 minutes on my a100 gpu so that's a pretty good gpu and if you don't have a gpu you're not going to be able to reproduce this uh on a cpu this would be um i would not run this on the cpu or a macbook or something like that you'll have to break down the number of uh layers and the embedding dimension and so on uh but in about 15 minutes we can get this kind of a result and um i'm printing some of the shakespeare here but what i did also is i printed 10 000 characters so a lot more and i wrote them to a file and so here we see some of the outputs so it's a lot more recognizable as the input text file so the input text file just for reference look like this so there's always like someone speaking in this manner and uh our predictions now take on that form except of course they're uh they're nonsensical when you actually read them so it is every crimty be a house oh those prepation we give heed um you know oh ho sent me you mighty lord anyway so you can read through this um it's nonsensical of course but this is just a transformer trained on the character level for one million characters that come from shakespeare so there's sort of like blabbers on in shakespeare like manner but it doesn't of course make sense at this scale uh but i think i think still a pretty good demonstration of what's possible so now i think uh that kind of like concludes the programming section of this video we basically kind of did a pretty good job and um of implementing this transformer but the picture doesn't exactly match up to what we've done so what's going on with all these additional parts here so let me finish explaining this architecture and why it looks so funky basically what's happening here is what we implemented here is a decoder only transformer so there's no component here this part is called the encoder and there's no cross attention block here our block only has a self-attention and the feed forward so it is missing this third in between piece here this piece does cross attention so we don't have it and we don't have the encoder we just have the decoder and the reason we have a decoder only uh is because we are just generating text and it's unconditioned on anything we're just we're just blabbering on according to a given data set what makes it a decoder is that we are using the triangular mask in our transformer so it has this auto regressive property where we can just go and sample from it so the fact that it's using the triangulate triangular mask to mask out the attention makes it a decoder and it can be used for language modeling now the reason that the original paper had an encoder decoder architecture is because it is a machine translation paper so it is concerned with a different setting in particular it expects some tokens that encode say for example french and then it is expected to decode the translation in english so so you typically these here are special tokens so you are expected to read in this and condition on it and then you start off the generation with a special token called start so this is a special new token that you introduce and always place in the beginning and then the network is expected to output neural networks are awesome and then a special end token to finish the generation so this part here will be decoded exactly as we we've done it neural networks are awesome will be identical to what we did but unlike what we did they want to condition the generation on some additional information and in that case this additional information is the french sentence that they should be translating so what they do now is they bring the encoder now the encoder reads this part here so we're only going to take the part of french and we're going to create tokens from it exactly as we've seen in our video and we're going to put a transformer on it but there's going to be no triangular mask and so all the tokens are allowed to talk to each other as much as they want and they're just encoding whatever's the content of this french uh sentence once they've encoded it they've they basically come out in the top here and then what happens here is in our decoder which does the uh language modeling there's an additional connection here to the outputs of the encoder and that is brought in through a cross attention so the queries are still generated from x but now the keys and the values are coming from the side the keys and the values are coming from the top generated by the nodes that came outside of the decode the encoder and those tops the keys and the values there the top of it feed in on the side into every single block of the decoder and so that's why there's an additional cross attention and really what it's doing is it's conditioning the decoding not just on the past of this current decoding but also on having seen the full fully encoded french um prompt sort of and so it's an encoder decoder model which is why we have those two transformers and an additional block and so on so we did not do this because we have no we have nothing to encode there's no conditioning we just have a text file and we just want to imitate it and that's why we are using a decoder only transformer exactly as done in gpt okay so now i wanted to do a very brief walkthrough of nano gpt which you can find on my github and uh nano gpt is basically two files of interest there's train.py and model.py train.py is all the boilerplate code for training the network it is basically all the stuff that we had here it's the training loop it's just that it's a lot more complicated because we're saving and loading checkpoints and pre-trained weights and we are decaying the learning rate and compiling the model and using distributed training across multiple nodes or gpus so the training.py gets a little bit more hairy complicated there's more options etc but the model.py should look very very similar to what we've done here in fact the model is is almost identical so first here we have the causal self-attention block and all of this should look very very recognizable to you we're producing queries keys values we're doing dot products we're masking applying softmax optionally dropping out and here we are pooling the values what is different here is that in our code i have separated out the multi-headed attention into just a single individual head and then here i have multiple heads and i explicitly concatenate them whereas here all of it is implemented in a batched manner inside a single causal self-attention and so we don't just have a b and a t and a c dimension we also end up with a fourth dimension which is the heads and so it just gets a lot more sort of hairy because we have four dimensional array tensors now but it is equivalent mathematically so the exact same thing is happening as what we have it's just it's a bit more efficient because all the heads are now treated as a batch dimension as well then we have the multilayer perceptron it's using the gelu non-linearity which is defined here except instead of relu and this is done just because opening i used it and i want to be able to load their checkpoints uh the blocks of the transformer are identical the communicate in the compute phase as we saw and then the gpt will be identical we have the position encodings token encodings the blocks the layer norm at the end the final linear layer and this should look all very recognizable and there's a bit more here because i'm loading checkpoints and stuff like that i'm separating out the parameters into those that should be weight decayed and those that shouldn't but the generate function should also be very very similar so a few details are different but you should definitely be able to look at this uh file and be able to understand a lot of the pieces now so let's now bring things back to chat gpt what would it look like if we wanted to train chat gpt ourselves and how does it relate to what we learned today well to train the chat gpt there are roughly two stages first is the pre-training stage and then the fine tuning stage in the pre-training stage we are training on a large chunk of internet and just trying to get a first decoder only transformer to babble text so it's very very similar to what we've done ourselves except we've done like a tiny little baby pre-training step and so in our case uh this is how you print a number of parameters i printed it and it's about 10 million so this transformer that i created here to create a little shakespeare um transformer was about 10 million parameters our data set is roughly one million uh characters so roughly one million tokens but you have to remember that open ai uses different vocabulary they're not on the character level they use these um subword chunks of words and so they have a vocabulary of 50 000 roughly elements and so their sequences are a bit more condensed so our data set the shakespeare data set would be probably around 300 000 tokens in the open ai vocabulary roughly so we trained about 10 million parameter model on roughly 300 000 tokens now when you go to the gpt3 paper and you look at the transformers that they trained they trained a number of transformers of different sizes but the biggest transformer here has 175 billion parameters uh so ours is again 10 million they used this number of layers in the transformer this is the n embed this is the number of heads and this is the head size of the size and then this is the batch size uh so ours was 65 and the learning rate is similar now when they trained this transformer they trained on 300 billion tokens so again remember ours is about 300 000 so this is about a million fold increase and this number would not be even that large by today's standards you'd be going up uh one trillion above so they are training a significantly larger model on a good chunk of the internet and that is the pre-training stage but otherwise these hyperparameters should be fairly recognizable to you and the architecture is actually like nearly identical to what we implemented ourselves but of course it's a massive infrastructure challenge to train this you're talking about typically thousands of gpus having to you know talk to each other to train models of this size so that's just the pre-training stage now after you complete the pre-training stage uh you don't get something that responds to your questions with answers and it's not helpful and etc you get a document completer right so it babbles but it doesn't babble shakespeare it babbles internet it will create arbitrary news articles and documents and it will try to complete documents because that's what it's trained for it's trying to complete the sequence so when you give it a question it would just uh potentially just give you more questions it would follow with more questions it will do whatever it looks like the some close document would do in the training data on the internet and so who knows you're getting kind of like undefined behavior it might basically answer with two questions with other questions it might ignore your question it might just try to complete some news article it's totally unaligned as we say so the second fine-tuning stage is to actually align it to be an assistant and uh this is the second stage and so this chat gpt block post from open ai talks a little bit about how this stage is achieved we basically um there's roughly three steps to this stage so what they do here is they start to collect training data that looks specifically like what an assistant would do so they are documents that have the format where the question is on top and then an answer is below and they have a large number of these but probably not on the order of the internet this is probably on the order of maybe thousands of examples and so they they then fine-tune the model to basically only focus on documents that look like that and so you're starting to slowly align it so it's going to expect a question at the top and it's going to expect to complete the answer and uh these very very large models are very sample efficient efficient during their fine-tuning so this actually somehow works but that's just step one that's just fine-tuning so then they actually have more steps where okay the second step is you let the model respond and then different raters look at the different responses and rank them for their preference as to which one is better than the other they use that to train the reward model so they can predict basically using a different network how much of any candidate response it would be desirable and then once they have a reward model they run ppo which is a form of policy policy gradient reinforcement learning optimizer to fine-tune this sampling policy so that the answers that gpt chat gpt now generates are expected to score a high reward according to the reward model and so basically there's a whole aligning stage here or fine-tuning stage it's got multiple steps in between there as well and it takes the model from being a document completer to a question answer and that's like a whole separate stage a lot of this data is not available publicly it is internal to open ai and it's much harder to replicate this stage and so that's roughly what would give you a chat gpt and nano gpt focuses on the pre-training stage okay and that's everything that i wanted to cover today so we trained to summarize a decoder only transformer following this famous paper attention is all you need from 2017 and so that's basically a gpt we trained it on a tiny shakespeare and got sensible results all of the training code is roughly 200 lines of code i will be releasing this code base so also it comes with all the git log commits along the way as we built it up in addition to this code i'm going to release the notebook of course the google collab and i hope that gave you a sense for how you can train these models like say gpt3 that will be architecturally basically identical to what we have but they are somewhere between 10 000 and 1 million times bigger depending on how you count and so that's all i have for now we did not talk about any of the fine tuning stages that would typically go on top of this so if you're interested in something that's not just language modeling but you actually want to you know say perform tasks or you want them to be aligned in a specific way or you want to detect sentiment or anything like that basically anytime you don't want something that's just a document completer you have to complete further stages of fine tuning which we did not cover and that could be simple supervised fine tuning or it can be something more fancy like we see in chat gpt we actually train a reward model and then do runs of ppo to align it with respect to the reward model so there's a lot more that can be done on top of it i think for now we're starting to get to about two hours mark so i'm going to kind of finish here i hope you enjoyed the lecture and yeah go forth and transform see you later